Superset RBAC Design for a 500-User Enterprise: Roles, Data Access and Dashboard Permissions

Superset’s permission model is fine-grained enough to express almost any access policy and coarse enough in its defaults that most deployments never use it properly. The result is familiar: everyone who builds anything is Alpha, everyone else is Gamma with datasource access granted one dataset at a time by whoever was asked, and nobody can say who can see the payroll table without clicking through the UI.This post is the design we use when a deployment has to serve several departments with different data, several kinds of user with different capabilities, and a security team that wants to read the policy rather than reverse-engineer it. It applies to Superset 3.x and 4.x.

How Superset permissions actually work

Superset inherits its security model from Flask-AppBuilder. Three concepts:

  • A permission is an action, such as can_read, can_write, can_export, menu_access, datasource_access, schema_access, database_access, all_datasource_access, all_database_access, can_sql_json.
  • A view menu is the thing the action applies to: a REST API (Dashboard, Chart, Dataset), a menu entry (SQL Lab, Settings), or a data object named like [analytics].[finance].[gl_entries](id:42) for a dataset or [analytics].[finance] for a schema.
  • A permission view is the pair, and a role is a set of permission views. Users hold any number of roles, and their effective permissions are the union.

Two consequences shape the design. First, because permissions are unioned, roles can be small and composable; a user gets capabilities from one role and data from another. Second, there is no deny. If any role grants access to a dataset, the user has it. Design for that.

Dataset permissions are created automatically when a dataset is created and named after it, so the permission list grows with the catalogue. Schema permissions (schema_access on [db].[schema]) cover every current and future dataset in that schema, which is the lever that makes the model scale.

The default roles and where they stop

Role What it grants Realistic use
Admin Everything, including security settings Two or three platform owners
Alpha Access to all data sources, create and edit charts and dashboards, no security settings Too broad for anyone in a multi-department deployment
Gamma Read charts and dashboards for data sources granted separately; no SQL Lab The right base for viewers and most builders
sql_lab SQL Lab access, layered on another role Analysts who write SQL
Public Applied to unauthenticated visitors Empty, unless you publish public dashboards deliberately

Alpha is the problem. It carries all_datasource_access, so an Alpha user sees every dataset in every database connected to Superset. The moment two departments share an instance, Alpha is a policy violation waiting to be discovered. The design below uses it for nobody.

The model: capability roles plus data-domain roles

Split roles into two families and assign at least one from each.

Capability roles: what a person can do

Role Built from Adds Removes
cap_viewer Gamma Nothing can_export on Chart and Dashboard if exports are restricted
cap_explorer Gamma can_explore on Superset, can_write on Chart (own charts), can_read on Dataset Dashboard editing
cap_builder Gamma Everything in explorer, plus can_write on Dashboard, can_read on CssTemplate
cap_analyst Gamma + sql_lab SQL Lab, can_sql_json, can_csv, saved queries Dashboard editing unless also a builder
cap_curator cap_builder can_write on Dataset, can_read on Database (to create virtual datasets and manage the catalogue) Database connection editing
cap_admin Admin

None of these grant any data. A user with only cap_builder can create a dashboard but has no datasets to put on it.

Data-domain roles: what a person can see

One role per data domain, granting schema_access on the schemas that belong to it, and nothing else:

Role Grants
data_finance schema_access on [warehouse].[finance], schema_access on [warehouse].[finance_marts]
data_sales schema_access on [warehouse].[sales]
data_ops schema_access on [warehouse].[operations]
data_hr_restricted datasource_access on specific HR datasets, not the schema, because the schema also contains payroll
data_shared schema_access on [warehouse].[shared_dims], the calendar, geography and product dimensions everyone needs

Prefer schema access. A new dataset created in the finance schema is visible to data_finance holders automatically, which is what the finance team expects. Use dataset-level access only when a schema contains a mix of sensitivities, and treat that as a signal to split the schema in the warehouse.

Putting them together

A finance analyst holds cap_analyst, data_finance, data_shared. A sales operations dashboard builder holds cap_builder, data_sales, data_ops, data_shared. A board member holds cap_viewer and data_finance. Adding a marketing department is one new data role and a mapping in the identity provider. Adding a new capability (say, alert creation) is one change to one capability role.

With five capability roles and ten domains you have fifteen roles, not fifty, and every one has a name a security reviewer can read.

Designing this for your actual org chart?

The capability/data-domain split above is the pattern; mapping it onto your specific teams, data domains, and SSO groups is the part that takes a workshop, not a blog post. A Superset Architecture Review does that mapping.

Book a Superset Architecture Review

Dashboard permissions

Data-domain roles decide which datasets a user can query. They do not by themselves control which dashboards appear in the list. Two mechanisms do:

Default behaviour. A user sees a dashboard if they have datasource access to every dataset on it (or the dashboard is published and they have access to at least one chart’s data, depending on version). This falls out of the data roles and is usually enough.

Dashboard RBAC. With the DASHBOARD_RBAC feature flag on, a dashboard owner can attach roles to a dashboard under its properties. Users in those roles can view the dashboard even if they lack datasource access to its datasets, for that dashboard only. This is how you publish an executive summary built on restricted data to a wider audience without granting them the underlying tables.

python
FEATURE_FLAGS = {
    "DASHBOARD_RBAC": True,
}

Use it deliberately. Because it bypasses dataset permissions, a dashboard with an over-broad role attached is a data exposure. Reserve the right to attach roles to curators, and review attachments quarterly (see the checks section).

Row-level security

RBAC decides which tables. Row-level security decides which rows. Under Settings, Row Level Security, a rule attaches a SQL clause to datasets for roles:

  • Regular rules add a filter for the listed roles: region = 'EMEA' on the sales datasets for data_sales_emea.
  • Base rules apply to everyone except the listed roles, which is how you filter by default and exempt a headquarters role.
  • Clauses can use Jinja: owner_email = '{{ current_username() }}' for per-user filtering, with ENABLE_TEMPLATE_PROCESSING on.

RLS composes with the role design cleanly: data_sales grants the tables, data_sales_emea (a role with no permissions at all, used only as an RLS handle) restricts the rows. For customer-facing multi-tenant deployments the considerations are different and covered in multi-tenant RLS for embedded Superset.

SQL Lab and database-level controls

SQL Lab lets analysts run arbitrary SQL, subject to the schemas their roles grant. Controls that matter at scale:

  • Per database connection, under Advanced, SQL Lab: expose in SQL Lab (off for databases nobody should query ad hoc), allow DML (off everywhere except a sandbox), allow file uploads (off).
  • SQL_MAX_ROW and DISPLAY_MAX_ROW in config, and per-database query timeouts, so one analyst cannot take down the warehouse.
  • schema_access is what limits which schemas appear in SQL Lab’s schema dropdown; database_access alone exposes every schema, so grant schemas not databases.
  • Consider user impersonation on the connection for warehouses that support it (Snowflake, BigQuery, Postgres roles). Superset then runs the query as the logged-in user, and the warehouse’s own audit log attributes it.

Feeding roles from SSO

Hand-assigning fifteen roles to five hundred people is where good designs die. Every capability and data role should map from a group in the identity provider through AUTH_ROLES_MAPPING, with AUTH_ROLES_SYNC_AT_LOGIN = True so that a group change takes effect at the next login. The Okta guide shows the mechanics; the design here is what the mapping targets:

python
AUTH_ROLES_MAPPING = {
    "bi-viewers": ["cap_viewer", "data_shared"],
    "bi-builders": ["cap_builder", "data_shared"],
    "bi-analysts": ["cap_analyst", "data_shared"],
    "finance-all": ["data_finance"],
    "sales-all": ["data_sales"],
    "sales-emea": ["data_sales_emea"],
    "bi-platform-admins": ["cap_admin"],
}

Group membership is now managed by the people who manage groups, with the identity provider’s approval workflow and audit trail, and Superset simply reflects it.

Roles as code

Clicking permissions into fifteen roles is error-prone and unrepeatable. Two ways to define them in configuration:

FAB_ROLES lets you declare roles as lists of regex pairs over view menu and permission names:

python
FAB_ROLES = {
    "cap_viewer": [
        [".*", "can_read"],
        ["Dashboard", "can_read"],
        ["Chart", "can_read"],
        ["Superset", "can_dashboard"],
        ["Superset", "can_slice"],
    ],
}

Roles declared here are created and kept in sync on superset init, and the config file becomes the policy document.

A provisioning script using the security manager’s API (add_role, find_permission_view_menu, add_permission_role) for the data-domain roles, run as part of deployment, reading the schema list from a YAML file. This is what we do for larger deployments because schema permissions are data-driven and a regex over [warehouse].[finance.*] is fragile.

Either way, keep the definition in version control and treat a role change like a code change: reviewed, tested in staging, deployed.

The checks that keep it honest

A role model drifts. These queries against the metadata database, run monthly, catch the usual drift:

  • Nobody holds Alpha. SELECT u.username FROM ab_user u JOIN ab_user_role ur ON u.id = ur.user_id JOIN ab_role r ON r.id = ur.role_id WHERE r.name = 'Alpha'. Expected: empty.
  • Admin count is small and known. Same query for Admin. Expected: the platform owners, nobody else.
  • No role grants `all_datasource_access` except Admin. Check ab_permission_view_role joined to permissions.
  • Every dataset’s schema is covered by exactly one data role, so that a new dataset is not accidentally visible through two domains.
  • Dashboard RBAC attachments list, with owners, for review.
  • Users with no data role (they can log in and see nothing), which usually means an SSO group mapping is missing.
  • Users not seen for 90 days, for deactivation.

Put the results in a dashboard. Superset is quite good at those.

Where to start if you have the everyone-is-Alpha deployment

  • Inventory users, roles and dataset permissions from the metadata database.
  • Define the data domains from the warehouse schemas, and the capability roles from what people actually do (most are viewers).
  • Create the new roles alongside the old ones, map SSO groups, and give a pilot department the new roles in addition to their old ones.
  • Verify the pilot sees what they should and nothing more, then remove their old roles.
  • Repeat per department. Remove Alpha last, once the last department is migrated.

Expect two to four weeks for a five-hundred-user deployment, most of it in conversations about who should see what, which is the conversation the deployment should have had at the start.

Frequently Asked Questions

Why is giving everyone the Alpha role a problem?

Alpha grants access to every dataset in the deployment, including ones added after the role was assigned, plus the ability to edit them. At fifty users that is untidy. At five hundred it means no one can answer the question an auditor actually asks, which is who can see a given table and why. The role model below exists so that question has an answer that does not depend on memory.

How many roles does a 500-user Superset deployment need?

Fewer than most teams expect, if the roles compose. Splitting them into capability roles (what a person can do) and data-domain roles (what a person can see) means a new department is one new data role rather than a full set of duplicates. A deployment of this size typically lands between twelve and twenty roles in total, not one per team.

Does row-level security replace role-based access control?

No, it narrows it. RBAC decides whether someone reaches a dataset at all; RLS decides which rows they see once they are there. They are designed to work together: a data-domain role grants the tables, and an RLS rule attached to a permission-free handle role restricts the rows. Using RLS alone to do both leaves the dataset itself reachable.

Can Superset roles be assigned automatically from Okta or Entra ID?

Yes, and they should be at this scale. Map every capability and data role to a group in the identity provider through AUTH_ROLES_MAPPING, and set AUTH_ROLES_SYNC_AT_LOGIN = True so a group change takes effect at the user’s next login. Access is then granted and revoked where the rest of your joiners-and-leavers process already lives.

Build It With Andolasoft

Role design is the second thing we look at in a Superset Architecture Review, after authentication: who has Alpha, how datasets are granted, whether RLS is doing what people think it is, and what the drift checks find. It is a fixed-scope, five-day review with a written report. If you would rather the role model were maintained for you, alongside patching and monitoring, that is Managed Support.

If you are looking at an everyone-is-Alpha deployment and an audit date, talk to us. We will map your current roles and dataset grants, show you where the real exposure is, and give you a fixed-scope plan to the model described above.
Multi-Tenant Row-Level Security in Embedded Superset: Three Patterns and When Each Fails

Embedding a Superset dashboard in your product is a few hours of work. Making sure that dashboard shows tenant A only tenant A’s rows, for every chart, every filter, every drill-down and every cached result, is the part that decides whether embedded analytics is a feature or an incident.Superset supports three distinct approaches. Teams often pick one because it was the first that worked, without knowing what it does not protect against. This post describes each, shows the configuration, and is specific about where it breaks. It ends with a test plan, because tenant isolation is one of the few things in analytics that you should prove rather than assume.

The setting

A typical embedded setup: your application authenticates its users, then asks Superset for a short-lived guest token scoped to a dashboard. The browser loads the dashboard in an iframe through the Embedded SDK, presenting that token. Superset runs the dashboard’s queries as a guest user with a fixed role and returns the results.

The tenant boundary can be enforced in three places along that path:

  • In the guest token, as RLS clauses your backend attaches when it mints the token.
  • In Superset’s RLS rules, attached to the guest role and parameterised with Jinja from the token’s user attributes.
  • In the data layer, by giving each tenant its own schema or database so that no single query can span tenants.

They are not mutually exclusive. The strongest deployments combine 1 or 2 with 3.

Pattern 1: RLS clauses in the guest token

When your backend requests a guest token, it can include rls clauses. Superset appends each clause to the WHERE of every query the dashboard runs, optionally restricted to one dataset.

json
POST /api/v1/security/guest_token/
{
  "user": { "username": "tenant-acme-user-42", "first_name": "Acme", "last_name": "User" },
  "resources": [{ "type": "dashboard", "id": "c1a4e2d7-...-dashboard-uuid" }],
  "rls": [
    { "dataset": 17, "clause": "tenant_id = 'acme'" },
    { "dataset": 23, "clause": "account_id IN (SELECT id FROM accounts WHERE tenant = 'acme')" }
  ]
}

The clause is SQL. Superset wraps it in parentheses and ANDs it with whatever the chart’s own filters produce.

Why teams like it: all tenant logic lives in your backend, next to the code that already knows who the user is. No Superset configuration per tenant. Adding a tenant is nothing.

Where it fails:

  • You are building SQL from application state. If tenant_id comes from anywhere the user can influence, or is interpolated without care, this is a SQL injection surface inside your security boundary. Derive the tenant identifier from your own authenticated session, never from a request parameter, and use a strict allow-list format (an integer, a UUID) rather than free text.
  • Clauses without a `dataset` apply to every dataset on the dashboard. If one dataset has no tenant_id column, that chart errors. Worse, if a dataset has a column by that name with a different meaning, the filter silently does the wrong thing. Always scope clauses to dataset IDs, and treat a new dataset on the dashboard as a change that needs a matching clause.
  • Virtual datasets. For a dataset defined by a SQL query, the RLS clause is applied to the outer query, not inside the subquery. If the inner SQL pre-aggregates across tenants, the outer filter cannot un-aggregate it. Virtual datasets used in embedded dashboards must keep tenant identifiers at their output grain.
  • Chart-level SQL escape hatches. Custom SQL in ad-hoc metrics or filters still runs inside the same query and is still wrapped by the RLS clause, so this is safe. But SQL Lab and the chart data API used outside the dashboard are not covered by a dashboard-scoped token. Make sure the guest role cannot reach them.
  • Token lifetime. Guest tokens default to a five-minute expiry. A token minted for tenant A and leaked is valid for tenant A’s data for that long. Keep the expiry short and mint tokens on demand, not in advance.

Pattern 2: Superset RLS rules with Jinja

Superset has its own row-level security feature under Settings, Row Level Security. A rule attaches a SQL clause to one or more datasets for one or more roles. The clause can use Jinja, and in an embedded context the interesting variables are the guest user’s attributes:

sql
tenant_id = (
  SELECT tenant_id FROM app_users WHERE username = '{{ current_username() }}'
)

Assign the rule to the guest role (GUEST_ROLE_NAME in superset_config.py), and every query the guest user runs against that dataset is filtered. Your backend puts the tenant-bearing username into the token and does nothing else. Requires ENABLE_TEMPLATE_PROCESSING = True.

Why teams like it: the tenant logic is declared once, in Superset, alongside the datasets it protects. Auditors can read it. A new dashboard on an existing dataset is protected automatically.

Where it fails:

  • The guest role is one role. Every embedded user shares it, so RLS rules cannot distinguish tenants by role. All the discrimination has to come through Jinja and the username, which means the username format is now part of your security model. Document it and validate it when minting tokens.
  • Jinja is a template, not a parameter. current_username() is interpolated into SQL. Superset’s built-in functions are safe, but a rule that interpolates anything user-controlled, such as url_param, is not. Never use url_param or dashboard filter values in an RLS rule; they are user input.
  • Every dataset needs a rule. A dataset added to an embedded dashboard without a rule is fully exposed. There is no default-deny. Put a check in your release process, or a script that lists embedded dashboards’ datasets without RLS rules.
  • Performance. The subquery runs inside every chart query. Index app_users.username, or precompute a mapping table, or the “secure” version of the dashboard is the slow one.
  • The lookup table is inside the analytics database. Your tenant mapping now has to be replicated into the warehouse and kept current. A stale mapping is either an outage or a leak, depending on the direction of the staleness.

Picked a pattern? Now stress-test the failure mode

Each RLS pattern above fails differently at real tenant counts and under caching. A Superset Embedding Feasibility Review pressure-tests your chosen pattern against your actual tenant model before it ships.

Request an Embedding Feasibility Review

Pattern 3: Physical isolation per tenant

Give each tenant its own schema (or database) and point tenant-specific datasets at them. Superset then cannot write a cross-tenant query because no single table contains two tenants.

Two ways to make this work with one set of dashboards:

  • Schema-per-tenant with dataset templating. Superset datasets and SQL templates can use Jinja for the schema name, but the guest token cannot switch schemas on its own. In practice this means one dashboard copy per tenant, generated by script from a template dashboard, each pointing at tenant datasets. The export and import API makes this manageable up to a few hundred tenants.
  • Database-per-tenant with connection-level identity. A separate Superset database connection per tenant, with credentials that can only see that tenant’s data. Combine with the dashboard-per-tenant approach above.

Why teams like it: the boundary is enforced by the database’s own permissions, not by SQL rewriting. A bug in Superset, a missed rule or a bad clause cannot cross it. Compliance conversations are shorter.

Where it fails:

  • Operational load. Hundreds of schemas, database connections and dashboard copies are a real maintenance burden. Dashboard changes must be re-propagated. Metadata database size grows with tenant count.
  • Cross-tenant features are impossible by construction. Benchmarking a tenant against an anonymised peer group, a common premium feature, cannot be done inside the isolated model. You end up building a separate aggregated dataset anyway, with Pattern 1 or 2 protecting it.
  • Provisioning is code you must write and maintain. New tenant means new schema, new connection, new dashboard import, all automated, all tested.

Choosing

Situation Recommendation
Tens to thousands of tenants, shared tables, moderate sensitivity Pattern 1 (token RLS), scoped to dataset IDs, with tenant IDs taken only from the server-side session
Dashboards change often, several teams add datasets Pattern 2 (Superset RLS) for default coverage, plus a release check that every embedded dataset has a rule
Regulated data, contractual isolation requirements, tenant count in the tens Pattern 3 (schema or database per tenant), with Pattern 1 as a second layer
Premium cross-tenant benchmarking Pattern 3 for tenant data, Pattern 1 on a separate pre-aggregated, anonymised dataset

Whichever you choose, apply two rules universally. First, the guest role has the minimum permissions: read on the specific dashboards, nothing on SQL Lab, nothing on the chart or dataset list endpoints. Second, dashboard-level native filters and URL parameters are user experience, never security; a filter can be removed by the user, an RLS clause cannot.

Caching

Superset caches chart data. If two tenants’ queries produce the same cache key, tenant B receives tenant A’s cached rows. Superset includes the query object, which contains the RLS clauses and the guest user context, in the cache key, so the standard patterns above are safe by design. Two things can still go wrong:

  • A custom cache key function or a plugin that builds its own cache key and omits the RLS context.
  • A caching layer outside Superset (a CDN, a reverse proxy cache) in front of the chart data endpoint.

Include a caching test in the plan below rather than reasoning about it.

The test plan

Isolation is testable. Run this before launch and on every change to dashboards, datasets, RLS rules or the token-minting code.

  • Two tenants, known data. Seed tenant A and tenant B with distinctive values you can search for in responses.
  • Positive test. Mint a token for A, load the dashboard, capture every chart data response, assert every row belongs to A.
  • Cross-tenant attempt. Using A’s token, call the chart data endpoint directly with a modified form data payload that removes or alters the tenant filter. Assert the response still contains only A’s rows.
  • Dataset coverage. List every dataset referenced by every embedded dashboard. Assert each has an RLS clause in the token or an RLS rule in Superset.
  • Cache test. Load the dashboard as A, then immediately as B, with identical filters. Assert B’s responses contain none of A’s distinctive values.
  • Expiry. Use an expired token and assert a 401, not stale data.
  • Role scope. Using a guest token, call the SQL Lab, dataset list and chart list APIs. Assert 403 on all of them.

Automate it. A guest token, a couple of HTTP calls and a few assertions fit in any CI pipeline.

Frequently Asked Questions

What is the safest way to isolate tenants in embedded Superset?

Physical isolation, a separate database or schema per tenant, is the strongest guarantee because a mistake in a filter cannot cross a boundary that does not exist. It is also the most expensive to operate. Guest-token RLS clauses are the usual choice for SaaS at scale, and they are safe when the token is minted server-side from the authenticated session and never accepts a tenant id from the browser.

Can one Superset instance safely serve many customers?

Yes, and most embedded deployments do. The conditions are that the tenant identifier comes from your own session rather than from the client, that every dataset in the embedded dashboard carries the isolating clause, and that the test plan below is run on every release. A single dataset without the clause is all it takes for the guarantee to fail.

Does query caching leak data between tenants?

It will if the cache key does not include the tenant. Superset caches on the query and its parameters, so two tenants issuing the same logical query can share a cache entry unless the RLS clause is part of the key. This is the single most commonly missed step in a multi-tenant embed and it does not show up in functional testing.

Do we need a separate database per tenant?

Usually not. A shared database with a tenant column and enforced RLS is adequate for most SaaS products and far cheaper to run. Separate databases earn their cost when a contract, a regulator or a data-residency requirement demands it, or when tenant data volumes differ enough that they need separate tuning.

Build It With Andolasoft

Tenant isolation is one part of an embedded implementation, alongside theming, the token service, SDK integration and event wiring. Our embedded analytics implementation package delivers all of it as a fixed scope, and it starts with a feasibility review in which the tenancy model is the first thing we look at. If your dashboards are already embedded and you want the isolation checked, the Architecture Review covers RLS and role design. The broader controls are in our post on governance and security for Superset deployments.

If you are embedding Superset into a product and want the tenancy model checked before it ships, talk to us. We will review your token service, datasets and cache configuration against the failure modes above, and give you a written plan to close any gaps.

How to Add Collaboration Features to Apache Superset

Apache Superset has become one of the most widely deployed open-source analytics platforms in the world. It connects to virtually any SQL database, renders rich interactive dashboards, and costs nothing per seat. But teams that adopt it quickly discover a gap: Superset ships without built-in Apache Superset collaboration features. Analytics is a team sport, yet Superset, out of the box, is built for viewing, not for discussing. There are no dashboard comments and no way to annotate a chart. There is also no folder tree to organise a growing library of dashboards.

The result is familiar to anyone who has run a review meeting from a BI tool. Someone screenshots a chart, pastes it into an email or chat thread, and circles the anomaly in a paint tool. The discussion about the data happens everywhere except next to the data. Context is lost, and decisions go undocumented. Three weeks later, nobody remembers why anyone queried the number or what the team agreed.

This article explains what Superset offers natively, plus three practical ways to add Apache Superset collaboration features on top of it. It also shows how Andolasoft builds them as clean, upgrade-safe extensions for enterprise clients.

What Superset Supports Natively, and Where the Gaps Are

Superset’s native collaboration surface is real but thin. Dashboards can be shared by link and published or kept as drafts. Ownership controls who can edit them. Tags let you label dashboards and filter the list page. Role-based access control and row-level security govern who sees what. Alerts and reports can be emailed or rendered in a dashboard on a schedule.

What is missing is the conversational layer: no inline comments, no visual markup, no review workflow, and no hierarchical folders. Tags can stand in for folders on the list page. But business users outside BI tools find a flat, filterable list a poor substitute for a browsable library. These gaps are consistently the top adoption complaints from non-technical stakeholders.

Three Ways to Add Apache Superset Collaboration Features

1. Pinned Comments and Visual Annotations on Dashboards

The highest-value addition is an in-dashboard markup layer. A reviewer opens a dashboard and clicks the exact chart in question. They pin a comment there, with a priority and a status, so the team can track it to resolution. Alongside pins, a drawing toolkit adds boxes, arrows, freehand marks, highlights, and text. Reviewers can mark up the live dashboard the way they would mark up a PDF. They can then save the annotation set for others to see.

Mechanically, a lightweight companion app delivers this feature inside Superset itself. It renders the target dashboard in an overlay and stores pins and drawings in your own database. Because it runs behind Superset’s session, the system attributes every comment to an authenticated user. And because it reuses Superset’s authentication, enabling Single Sign-On for Superset also enables it for the markup layer. Reviewers who never build charts just need a URL, their corporate login, and a pencil.

collaboration_markup

2. Folder-Style Navigation with Previews, Tags, and Search

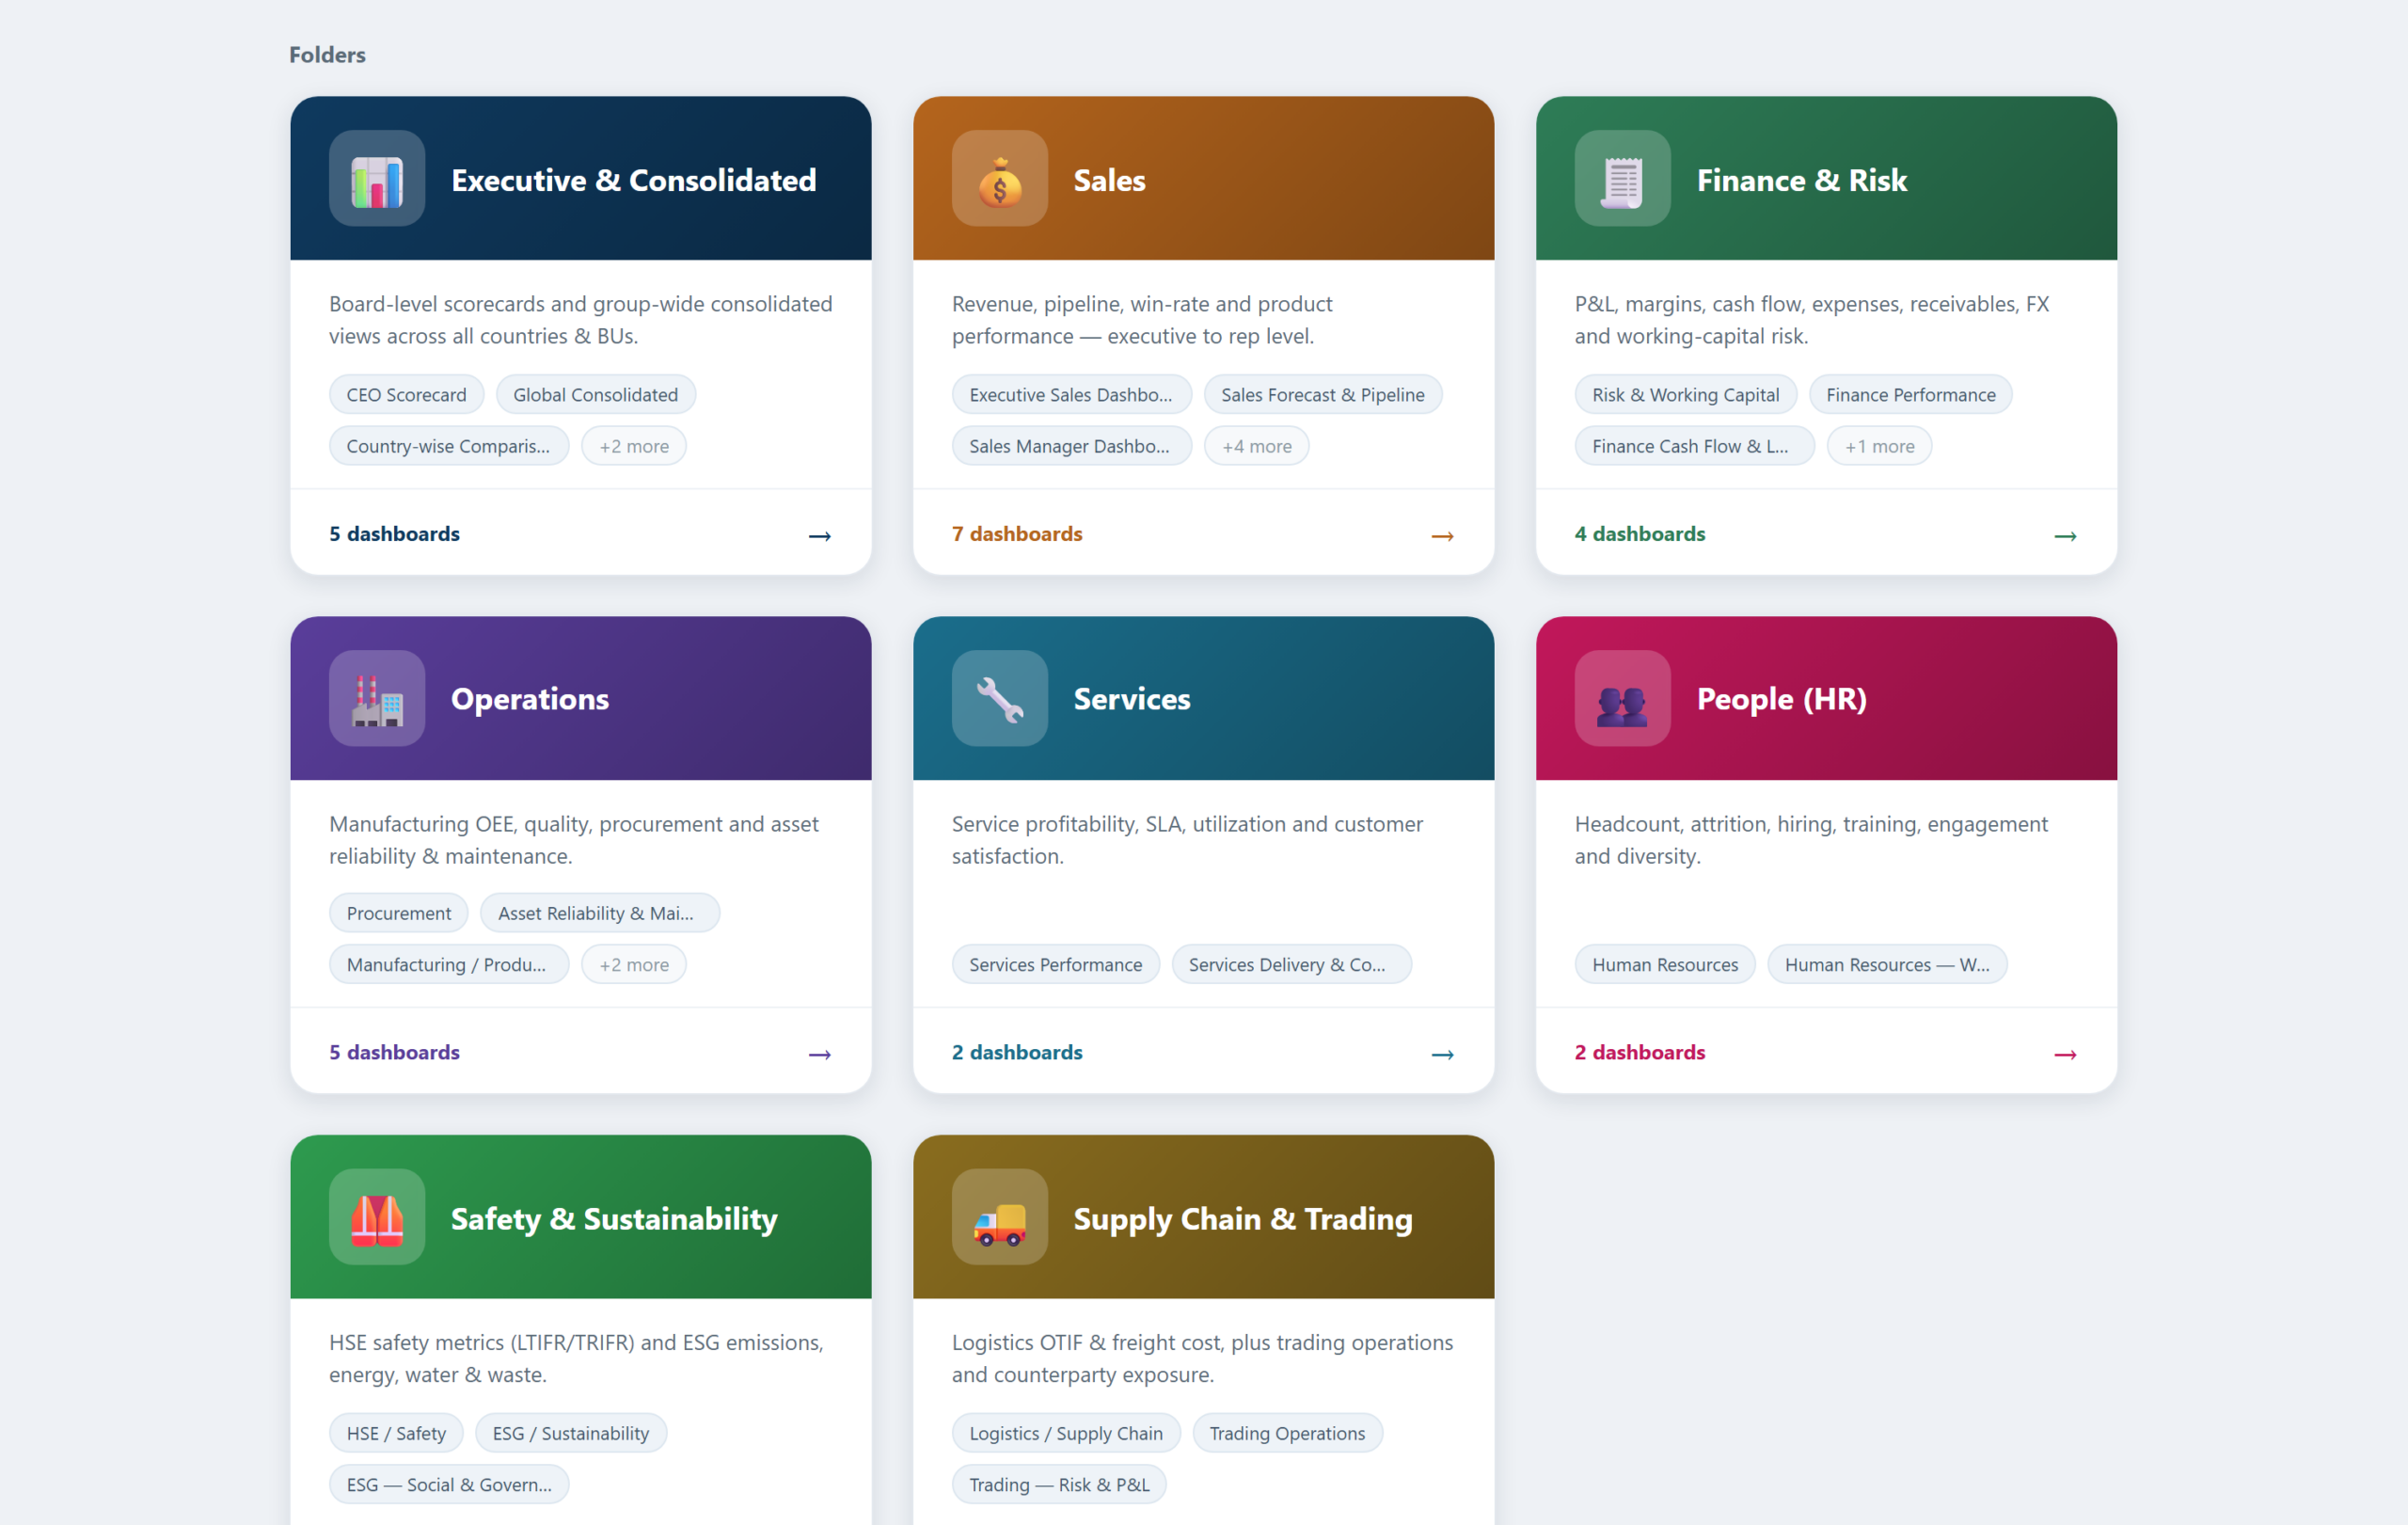
The second addition solves discovery. A folder app presents the dashboard estate as a set of coloured folder cards, one per function. Examples include Executive, Sales, Finance, and Operations. Opening a folder shows each dashboard as a card with a live preview thumbnail, its tags, and a chart count. Clicking a card opens a full preview with a jump-through to the real dashboard. A search box filters across every folder by title or tag.

collaboration_folders

The important design decision: folders generate live from the dashboard titles and tags already in Superset. The library maintains itself. Publish a new dashboard, and it appears in the right folder immediately, complete with its preview and tags. It’s instantly searchable too. No curator required.

3. Tags, RBAC, and Row-Level Security as the Governance Layer

Collaboration without governance becomes noise. The third layer is configuration, not code. A tag taxonomy, organised by department and by audience, powers both the native list filters and the folder app. Roles separate admins, editors, and viewers. Row-level security lets a country manager see their country and a business-unit head see their unit. Single Sign-On ties all of it to the corporate identity provider. Together, these controls make the collaborative layer trustworthy: every comment is attributable, and nobody annotates data they should not see.

How Andolasoft Builds Apache Superset Collaboration Features, Upgrade-Safely

The naive way to add features to Superset is to fork it and edit the source. That works until the next Superset release, at which point every upgrade becomes a merge conflict. Our implementations follow a stricter rule: never patch core.

  • Extensions, not forks: Flask blueprints deliver the comment, annotation, and folder apps alongside Superset. They use its session, authentication, and metadata, but touch none of its source files.
  • Your data, your database: pins, drawings, and folder definitions live in your PostgreSQL database. The team versions and backs them up with everything else.
  • Upgrade-safe by construction: we modify nothing in the core. A Superset version upgrade becomes a container-image bump plus a regression pass, not a re-implementation.
  • Security inherited, not duplicated: the apps inherit Superset’s login, so SSO, roles, and row-level security apply automatically.

What Changes for the Team

  • Reviews happen in context: feedback lands on the exact chart, with an author and a timestamp. It replaces the old screenshot thread.
  • Meetings get shorter: pre-meeting comments mean the meeting starts at the decision, not at the description of the problem.
  • Nothing falls through the cracks: comments carry a status. The team either resolves each query or leaves it visibly open.
  • The library invites browsing: non-technical users navigate a folder library with previews and search instead of a flat list. Adoption follows.

Frequently Asked Questions

Can You Add Apache Superset Collaboration Features Like Comments?

Not natively. In practice, though, a lightweight companion app can add Apache Superset collaboration features to any dashboard. These include pinned comments and visual annotations. It runs on Superset’s own login and SSO, and stores everything in your own database.

Does Superset have folders for dashboards?

No. Tags provide folder-like filtering on the dashboard list. A custom folder app can add full card-based navigation, with live previews, tags, and search. It generates automatically from the dashboards you already have.

Will Apache Superset Collaboration Features Break on Upgrade?

Not if you build them as extensions rather than source patches. Flask-blueprint apps that sit alongside an unmodified Superset core survive version upgrades with a simple regression pass.

Do reviewers need a Superset licence or training?

Superset is open source, so there are no licences at all. Reviewers need only a corporate login and a URL. Commenting and annotating require no chart-building knowledge.

Build It With Andolasoft

Andolasoft designs and deploys governed, board-ready analytics platforms on Apache Superset for manufacturing and industrial companies. See our detailed Superset dashboard templates for manufacturing KPIs for an example. Our BI practice covers the full lifecycle: KPI modelling to global standards (ISO 22400, SCOR, GRI) and data modelling with conformed dimensions. It also includes department dashboards with direction-aware RAG scorecards, row-level security, and Single Sign-On. Folder navigation and the Apache Superset collaboration features covered above round out the platform. Because Superset is open source, the entire platform runs without per-seat licence fees. The investment goes into your KPIs, not licences.

If your leadership team is still waiting for month-end spreadsheets, talk to us. We will stand up a working demo on a representative dataset and walk your stakeholders through it. Then we’ll give you a clear, fixed-scope plan to production.

Apache Superset Dashboard Templates for Manufacturing KPIs

Every manufacturing BI programme faces the same opening question: where do we start? Starting from a blank canvas means months of workshops before anyone sees a chart, and the first drafts inevitably reflect whoever shouted loudest rather than what the industry has already standardised. Starting from proven templates inverts the problem. The right KPIs, layouts, RAG thresholds and filters arrive on day one, and the workshops become a review exercise: confirm, adjust, connect to your data.

This article walks through a complete template library for Apache Superset that we use as the starting point for manufacturing clients: eight functional folders, roughly thirty dashboards, every KPI aligned to a recognised standard such as ISO 22400 for plant performance, SCOR for supply chain, ISO 9001 for quality, and GRI for sustainability reporting.

Why Start From a Template Library

  • Faster time to value: a working dashboard in days, a full suite in weeks. The slow part of BI is agreeing on definitions, and templates arrive with defensible, standards-based definitions already written.
  • Best practice baked in: each template encodes what world-class reporting looks like for its function, so you inherit the collective practice of an industry rather than reinventing it.
  • Consistent design language: every template opens with a KPI band, then gauges, then trend and breakdown analysis, then a scorecard table. Users learn the grammar once and can read any dashboard in the suite.
  • Standard filters: the same Date, Country, Business Unit, and Department filters appear everywhere, so any two views reconcile and cross-functional questions get answered without new extracts.
  • Targets included: RAG thresholds ship with sensible industry defaults (OEE green at 75 percent and above, scrap red above 3.5 percent, and so on) and are adjusted to your targets during onboarding.

Apache Superset Dashboard Templates

The Template Library at a Glance

Folder / Template Set Included Dashboards Headline KPIs
Executive & Consolidated CEO scorecard, global consolidated, country comparison, business-unit comparison Revenue, EBITDA, cash, OEE, LTIFR, carbon intensity
Sales Executive, manager, rep, product, forecast & pipeline, win/loss & velocity, customer & account Win rate, weighted pipeline, coverage, NRR, book-to-bill
Finance & Risk Finance performance, expense analysis, cash flow & leverage, risk & working capital Margins, DSO, free cash flow, quick ratio, AR aging
Operations Production (OEE), cost & flow, quality, procurement, asset reliability & maintenance OEE, unit cost, six losses, CAPA, PM compliance
Services Services performance, delivery & contracts SLA, CSAT, utilization, realization, renewal
People (HR) Human resources, workforce cost & talent Attrition, eNPS, revenue per employee, diversity
Safety & Sustainability HSE/safety, ESG environmental, ESG social & governance LTIFR, TRIFR, Scope 1-3, ISO 45001 / 14001
Supply Chain & Trading Logistics, trading operations, trading risk & P&L OTIF, freight per tonne, mark-to-market, VaR

Inside the Operations Templates

Production / OEE Template (ISO 22400)

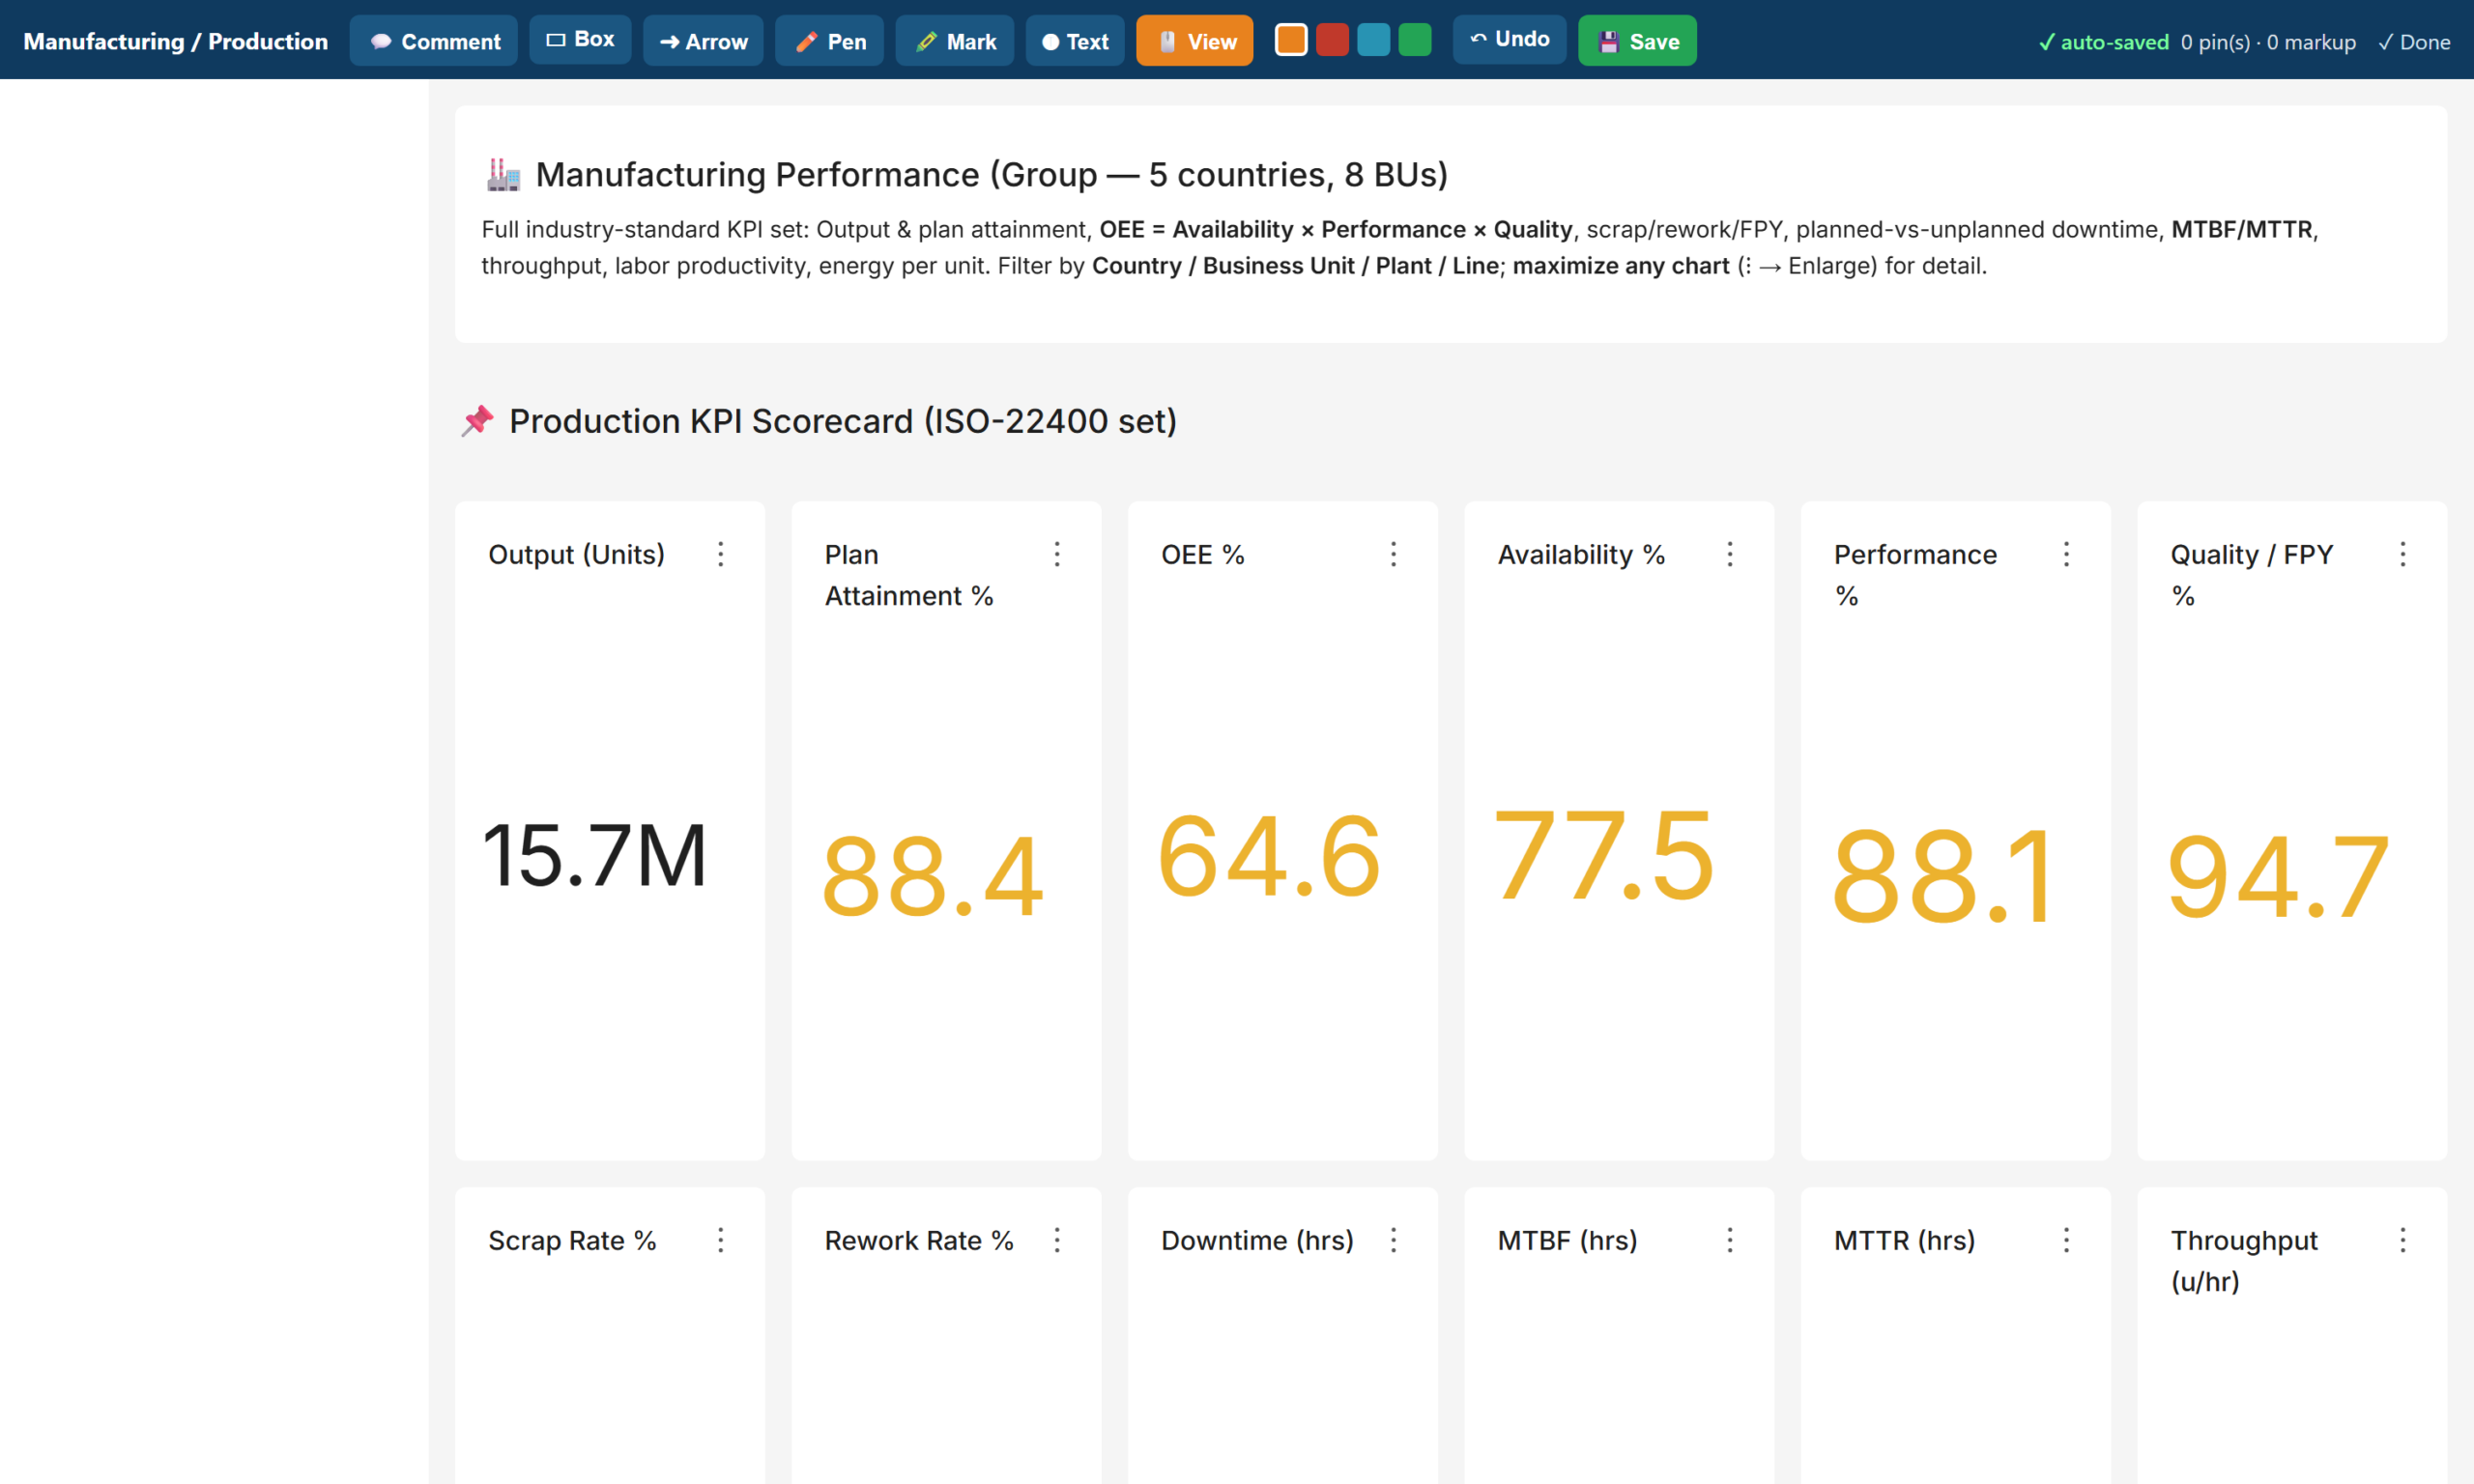
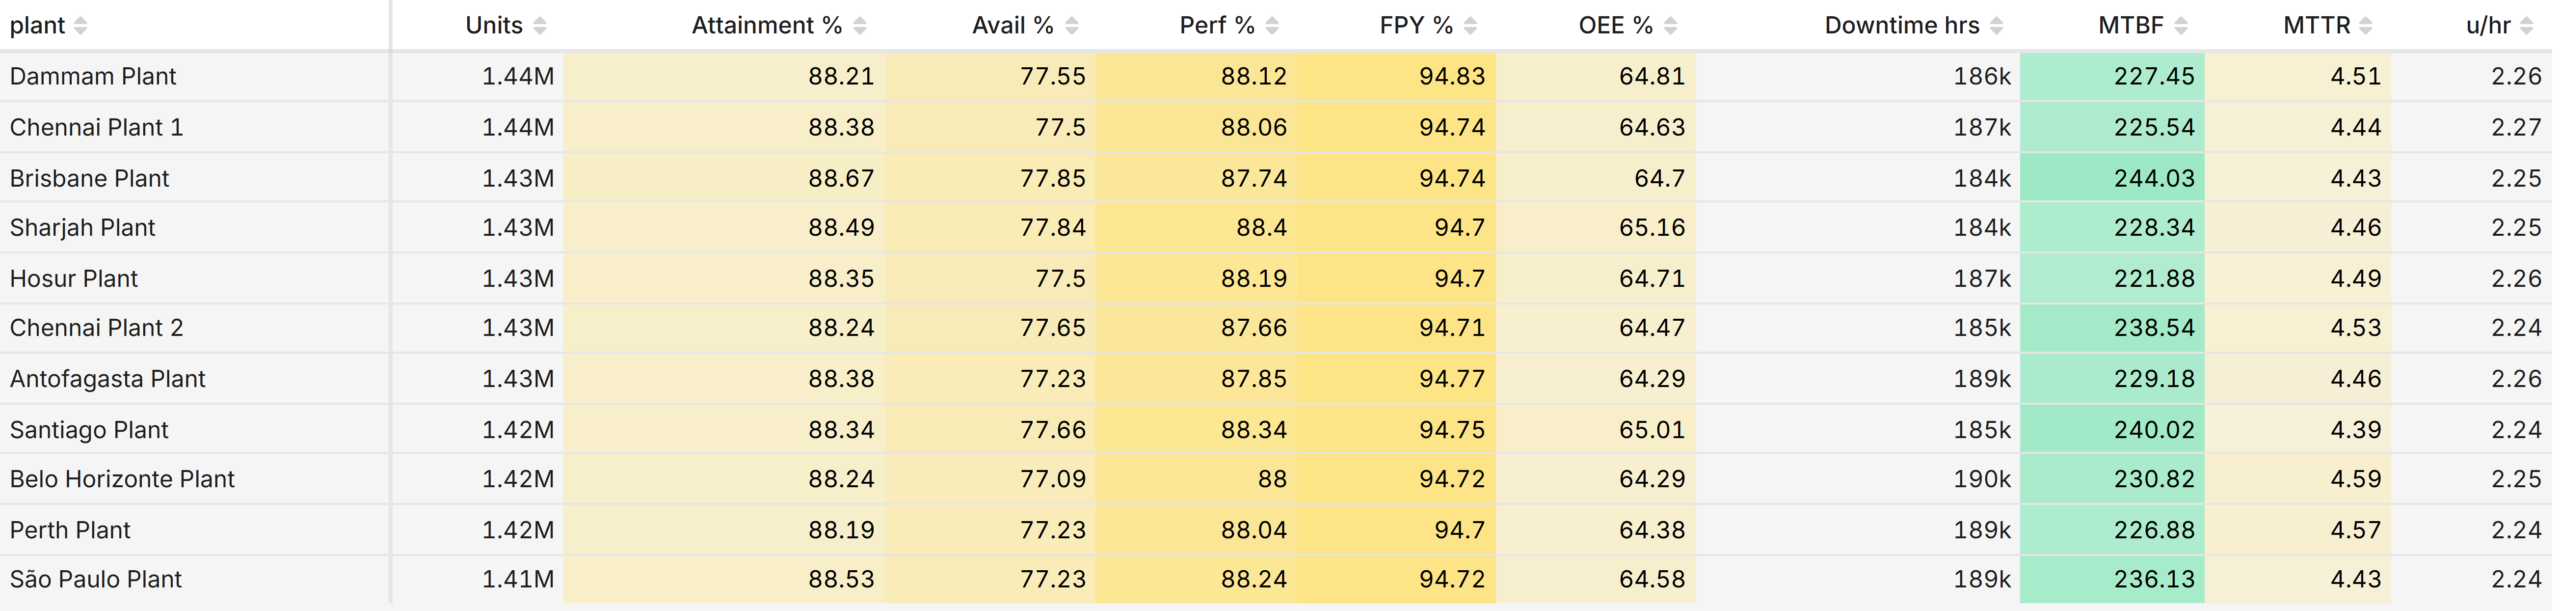
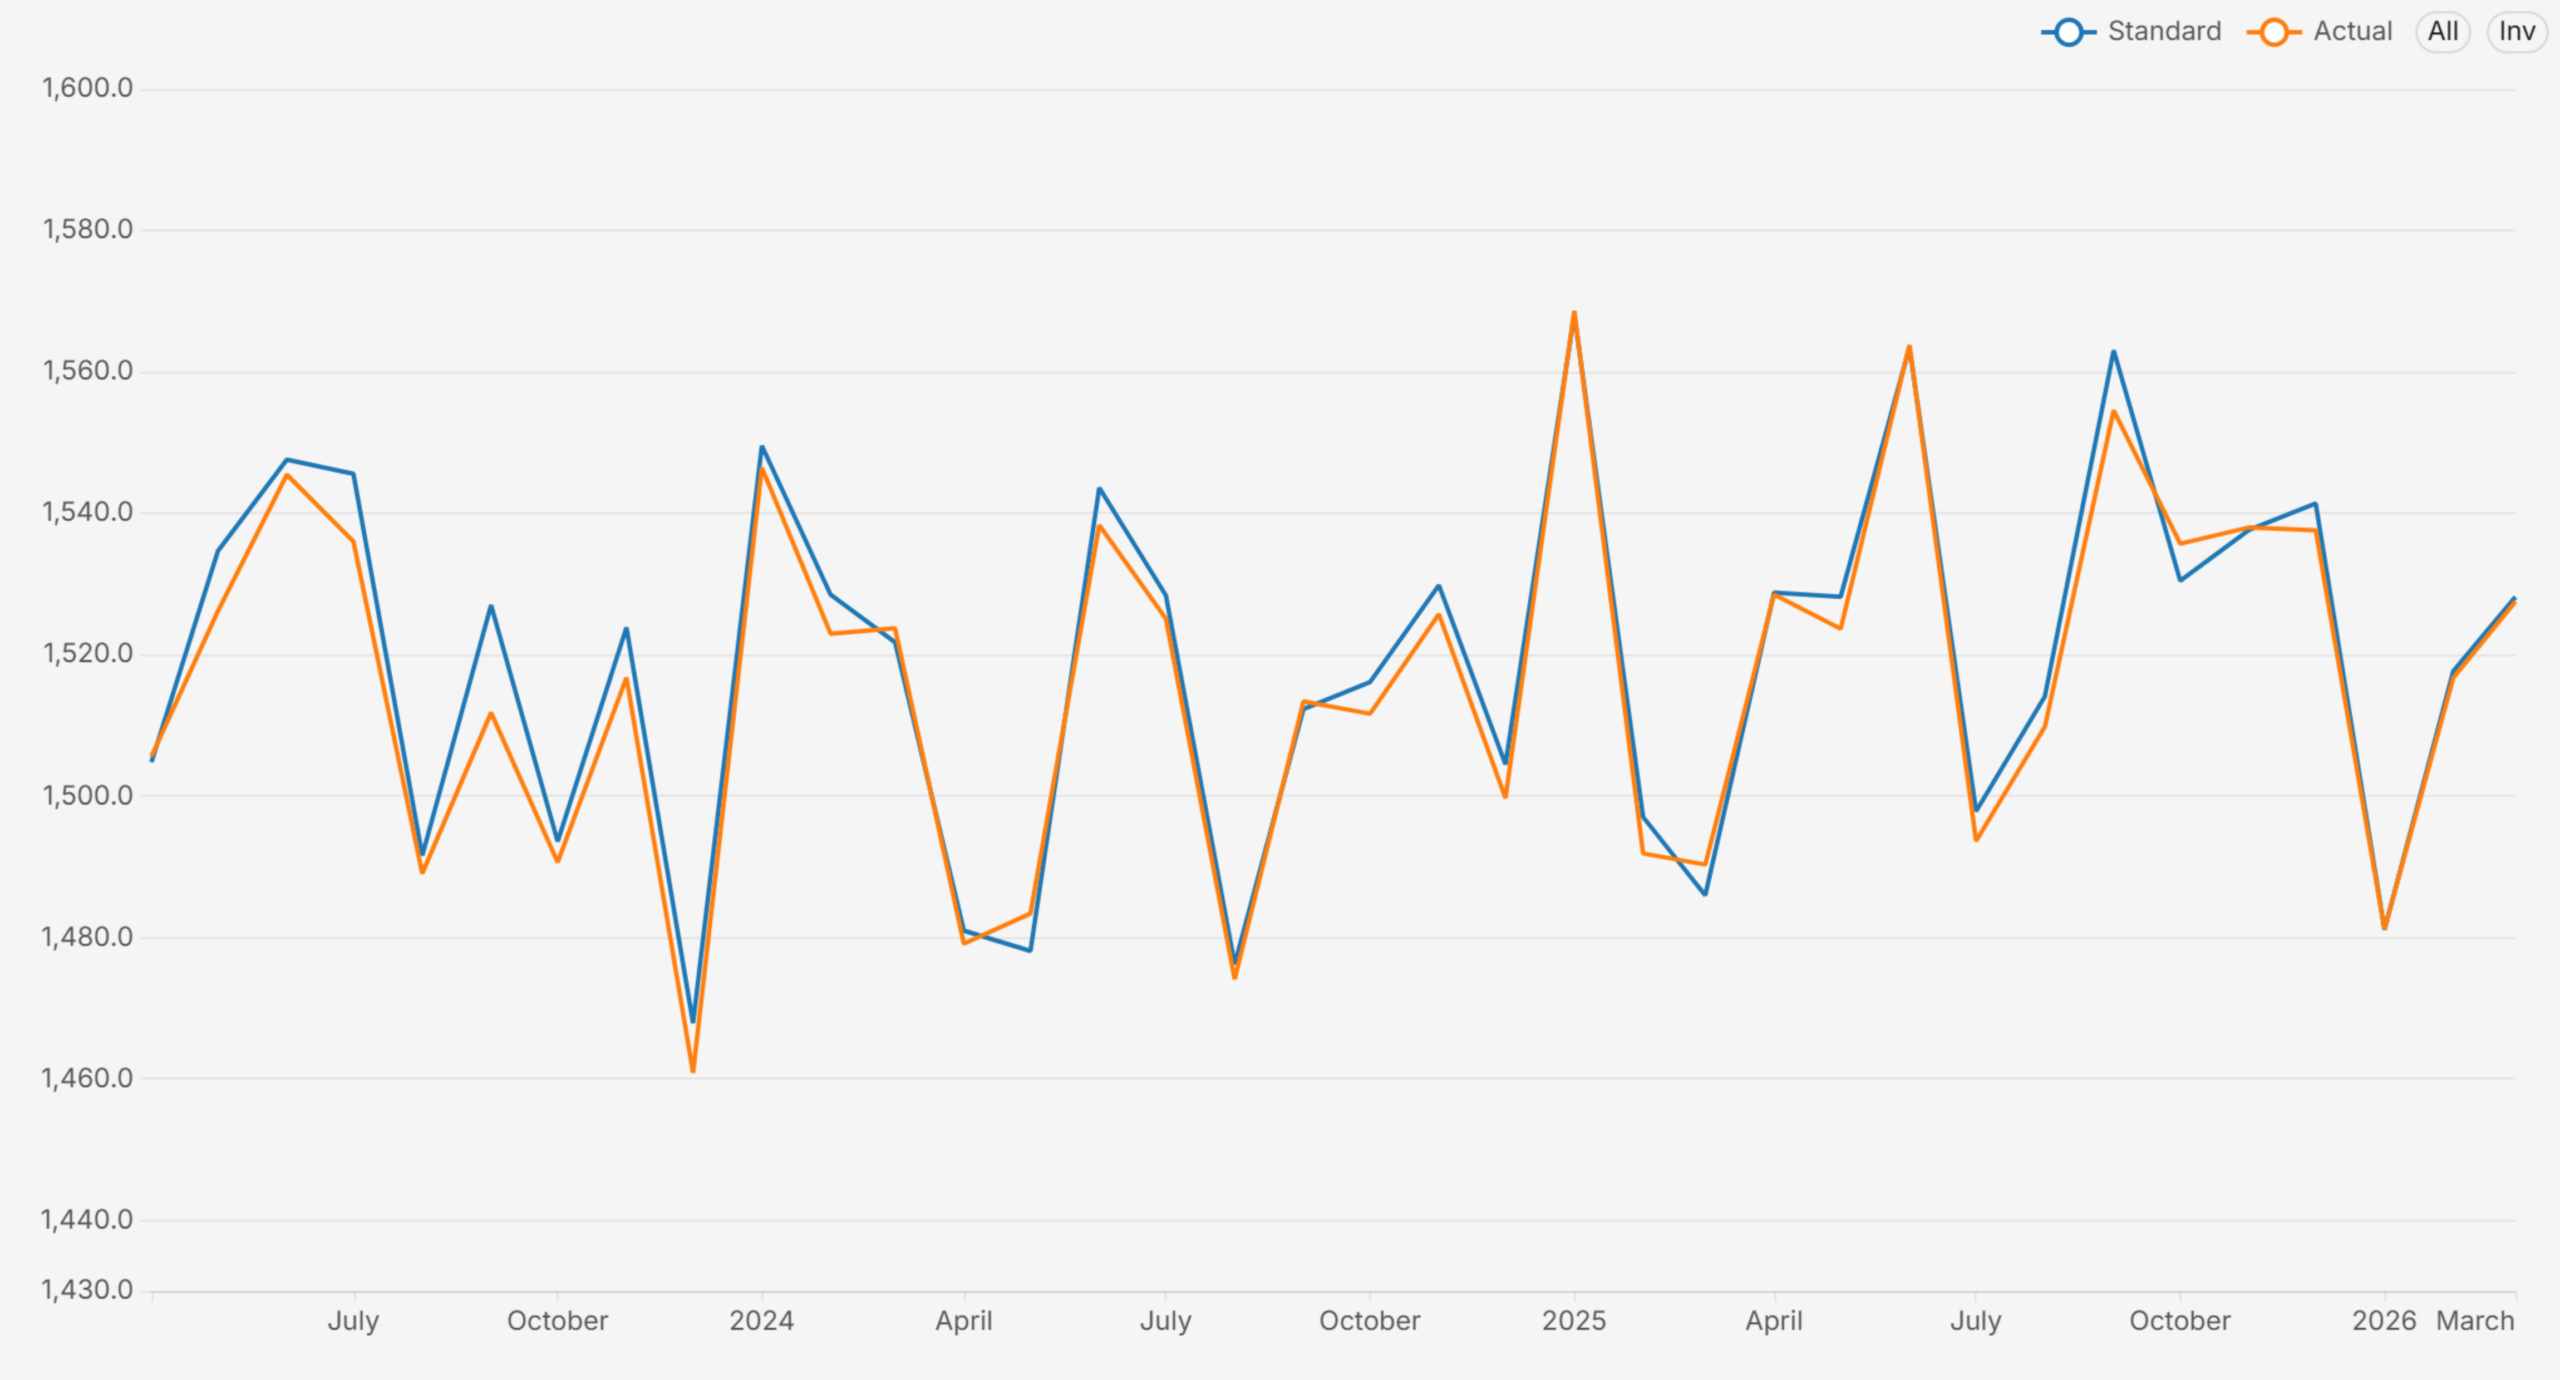
The anchor template. A twelve-tile KPI band covers output, plan attainment, OEE with its availability, performance and quality components, scrap and rework rates, downtime hours, MTBF, MTTR, and throughput. Below it: output versus plan trend, OEE decomposition by plant, planned-versus-unplanned downtime with a Pareto by reason, and plant and line scorecard tables with direction-aware RAG. This is the dashboard a plant head opens every morning. Apache Superset Dashboard Templates

Cost & Flow Template (Lean / TPM)

OEE tells you how much you lost; cost and flow tell you what it cost and where the flow breaks. This template adds unit cost of production against standard cost with variance percentage, a stacked cost breakdown (material, labour, energy, overhead, cost of poor quality), the classic Six Big Losses by plant, cycle time against takt time, capacity utilization, work-in-progress, and on-time delivery. Together, the two templates turn a plant-efficiency board into a genuine operations board. Apache Superset Dashboard Templates

Quality, Procurement and Maintenance Templates

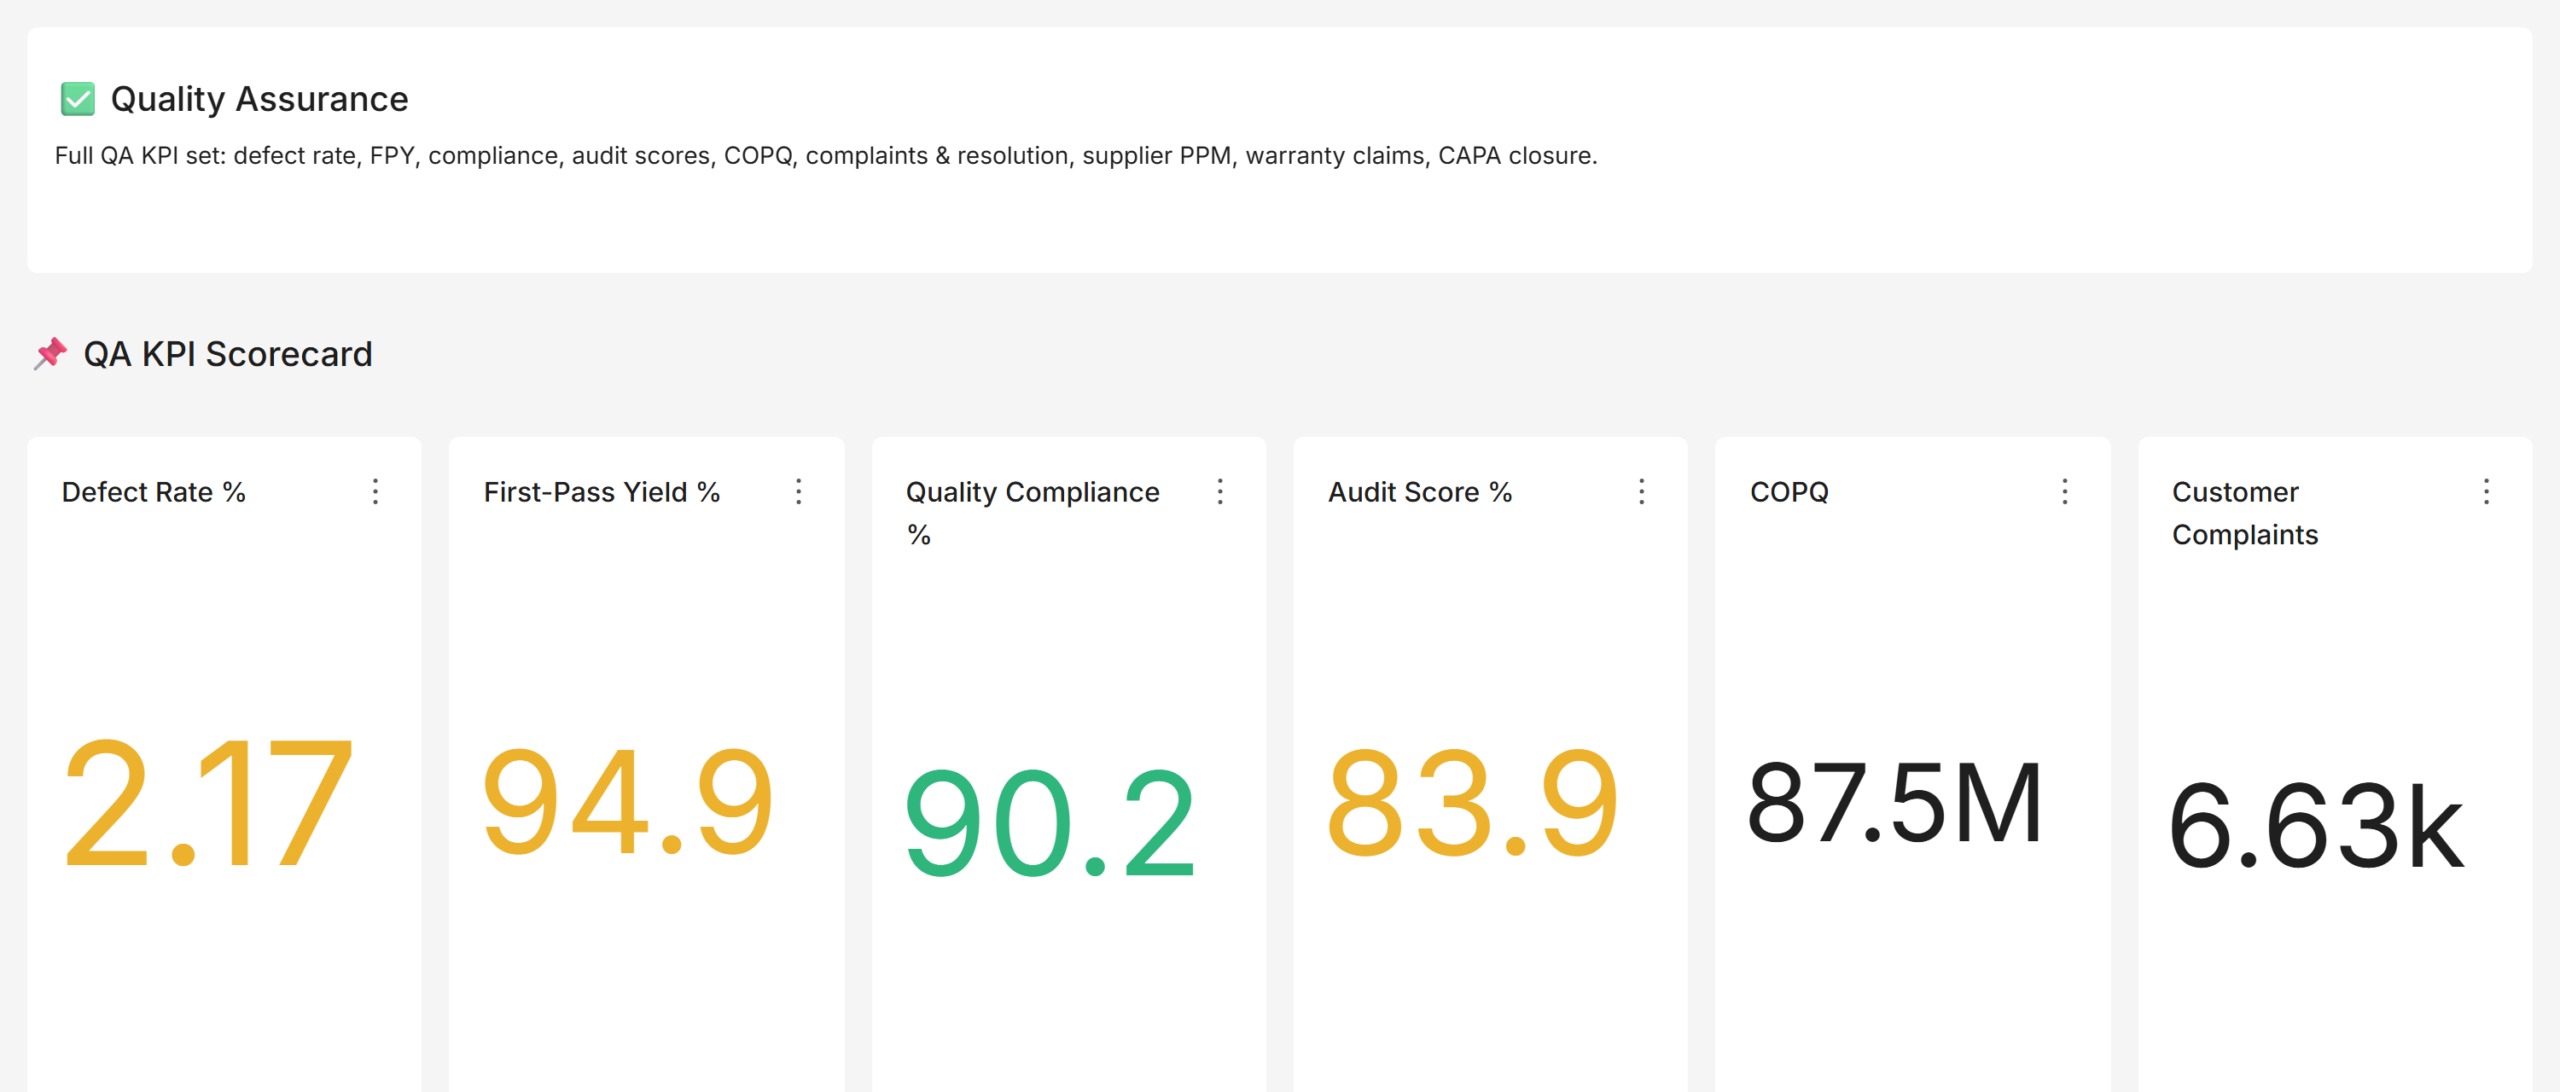
The quality template tracks defect rate, first-pass and rolled throughput yield, CAPA closure, audit scores, supplier defect PPM, and the cost of poor quality. The procurement template covers savings, vendor on-time and quality performance, emergency purchase share, spend under contract, and material availability. The maintenance template extends MTBF and MTTR with preventive-maintenance compliance, backlog, breakdown events, and the planned-versus-reactive ratio, the leading indicators that predict next quarter’s downtime.

Beyond Operations: Sales, Finance, and the Board-Level Domains

Manufacturing BI programmes often stop at the plant gate, which is a mistake: the same disciplines apply to the commercial and corporate functions, and the board reads them all on one page.

The sales templates layer the commercial view the way mature sales organisations do: an executive revenue view, a manager view with leaderboards and pipeline funnels, a rep view for personal performance, and dedicated dashboards for forecast and pipeline (weighted pipeline, coverage against quota, commit and best-case categories), win/loss and velocity (stage conversion, loss reasons, sales cycle), and customer and account health (net revenue retention, churn, backlog and book-to-bill, the KPI pair every industrial board asks about).

The finance templates go beyond the profit-and-loss basics into the balance-sheet strength a multinational needs: a cash flow and leverage view (operating, investing and financing cash flow, free cash flow, quick ratio, debt-to-equity, interest coverage) and a risk and working capital view (receivables aging, currency exposure and hedging, inventory days of supply, supplier concentration). The safety and sustainability templates complete the board pack with LTIFR and TRIFR, the incident pyramid, Scope 1 to 3 emissions, energy and water intensity, and certification coverage, the domains that regulators and lenders now expect as first-class reporting.

The Executive Layer

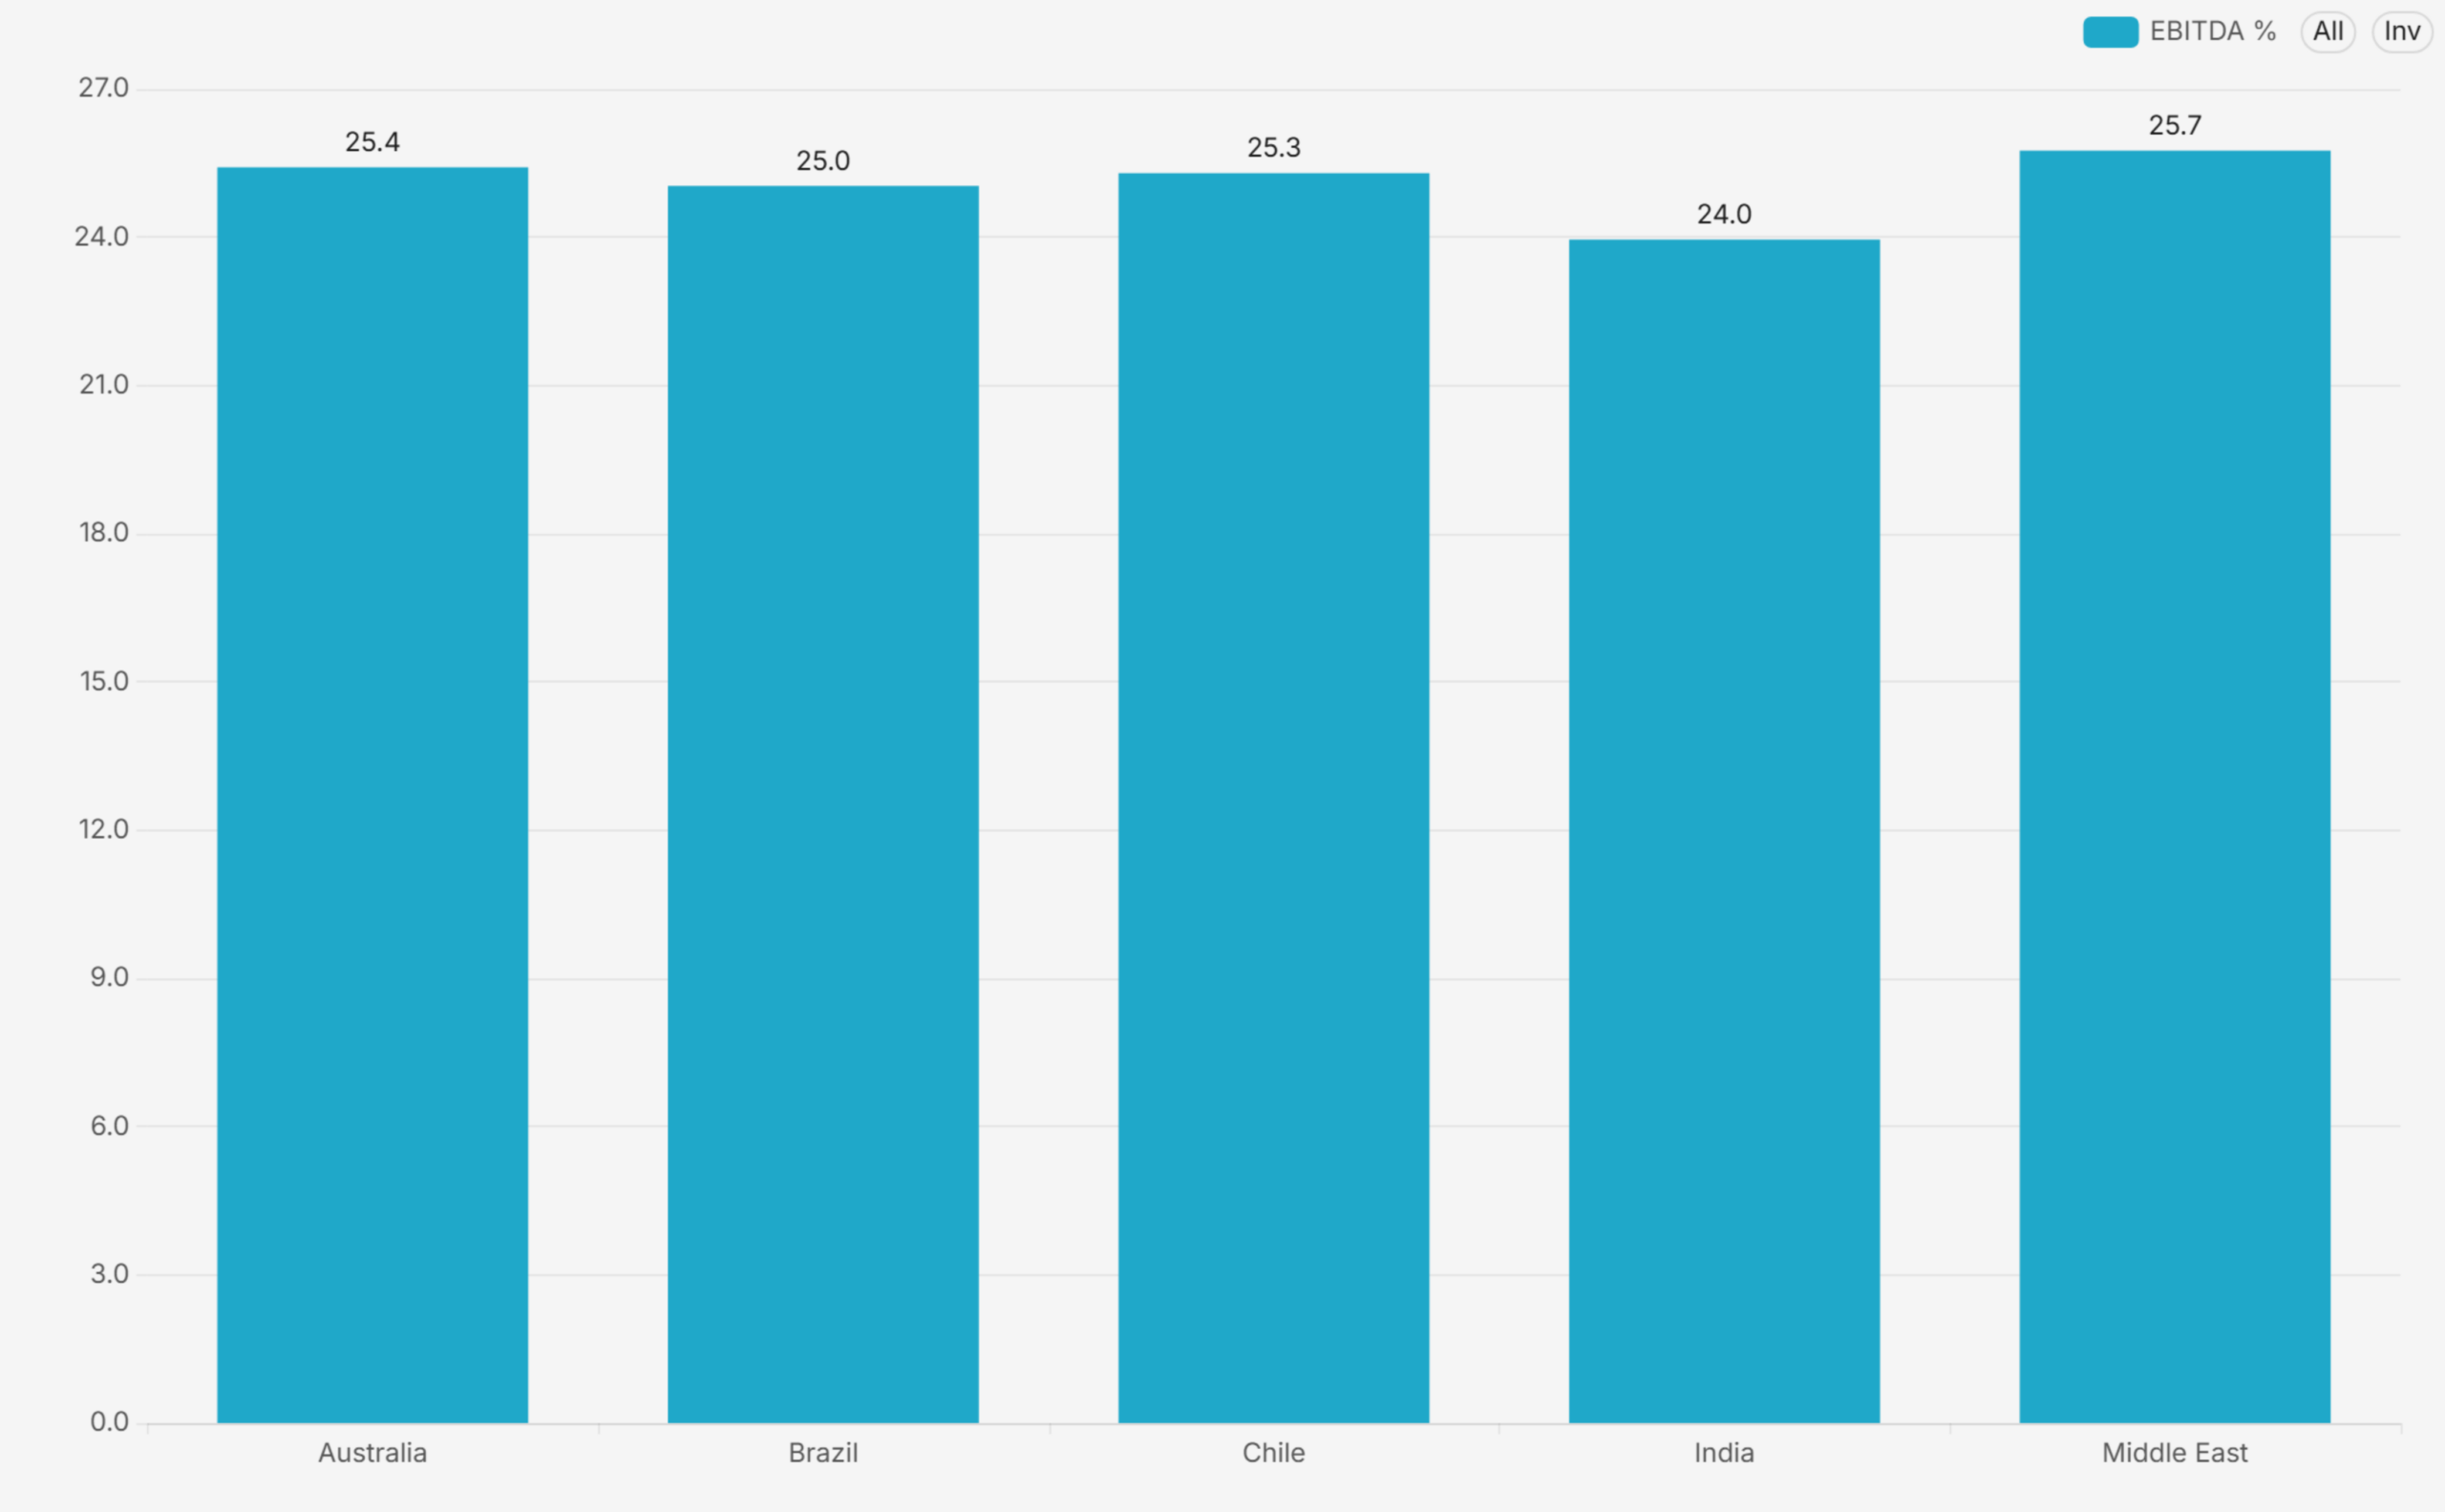
The executive templates roll one headline KPI per function onto a single page with RAG status, then provide consolidated, country-comparison, and business-unit-comparison views built on the same definitions. Because every template shares conformed dimensions, the group view and the plant view cannot disagree, and a board question about any tile drills straight into the owning department’s template without changing tools or definitions. Apache Superset Dashboard Templates

Common Mistakes When Adopting Templates

  • Skipping the definition review: copying a template without confirming the KPI formula with the owning function. The template is a starting position, not a decree; a fifteen-minute review per KPI buys lasting trust in the numbers.
  • Ignoring data grain: loading data at the wrong grain. If the template expects monthly plant-line data and the source provides only monthly plant totals, drill-downs silently mislead. Match the grain before go-live.
  • Not pruning: keeping every template even where a function does not exist. An empty dashboard erodes confidence in the full suite; prune what does not apply.
  • Frozen thresholds: treating RAG defaults as final. Industry defaults make the suite readable on day one, but each business sets its own ambition; recalibrate thresholds at the first quarterly review.

How to Customise the Templates to Your Business

  • Point at your data: connect the certified datasets to your ERP, MES, QMS, CMMS, and HR sources. The templates are source-agnostic; only the dataset layer changes.
  • Confirm definitions: review each KPI formula with the owning function and set your targets and RAG thresholds. This usually takes one workshop per department.
  • Secure: apply row-level security so each country and business unit sees its own slice, and connect Single Sign-On to your identity provider.
  • Brand and prune: apply your logo and colour theme, organise the folders to match your operating model, and retire any template that does not apply.

A template-based rollout typically reaches a governed, adopted suite in six to eight weeks, roughly half the timeline of a from-scratch build, with materially lower definition risk.

Frequently Asked Questions

Are dashboard templates really faster than building from scratch?

Yes, primarily because the slow part of BI is not chart-building but definition-settling. Templates arrive with standards-based KPI definitions that functions can review and adjust, which converts months of debate into days of confirmation.

Can the templates work with our ERP and MES?

Yes. The templates sit on a dataset layer that is mapped to your sources during onboarding. Any system that can land data in a SQL database, which includes every mainstream ERP, MES, QMS, and CMMS, can feed them.

Do the templates include targets and RAG thresholds?

They ship with industry-default thresholds for every KPI, which are then tuned to your targets during the definition workshops. The RAG logic is direction-aware, so lower-is-better metrics colour correctly.

Build It With Andolasoft

Andolasoft designs and deploys governed, board-ready analytics platforms on Apache Superset for manufacturing and industrial companies. Our BI practice covers the full lifecycle: KPI modelling to global standards (ISO 22400, SCOR, GRI), data modelling with conformed dimensions, department and business-unit dashboards with direction-aware RAG scorecards, row-level security, Single Sign-On, folder navigation and in-dashboard collaboration. Because Superset is open source, the entire platform runs without per-seat licence fees, so the investment goes into your KPIs, not licences.

If your leadership team is still waiting for month-end spreadsheets, talk to us. We will stand up a working demo on a representative dataset, walk your stakeholders through it, and give you a clear, fixed-scope plan to production.