Superset RBAC Design for a 500-User Enterprise: Roles, Data Access and Dashboard Permissions

Superset’s permission model is fine-grained enough to express almost any access policy and coarse enough in its defaults that most deployments never use it properly. The result is familiar: everyone who builds anything is Alpha, everyone else is Gamma with datasource access granted one dataset at a time by whoever was asked, and nobody can say who can see the payroll table without clicking through the UI.This post is the design we use when a deployment has to serve several departments with different data, several kinds of user with different capabilities, and a security team that wants to read the policy rather than reverse-engineer it. It applies to Superset 3.x and 4.x.

How Superset permissions actually work

Superset inherits its security model from Flask-AppBuilder. Three concepts:

  • A permission is an action, such as can_read, can_write, can_export, menu_access, datasource_access, schema_access, database_access, all_datasource_access, all_database_access, can_sql_json.
  • A view menu is the thing the action applies to: a REST API (Dashboard, Chart, Dataset), a menu entry (SQL Lab, Settings), or a data object named like [analytics].[finance].[gl_entries](id:42) for a dataset or [analytics].[finance] for a schema.
  • A permission view is the pair, and a role is a set of permission views. Users hold any number of roles, and their effective permissions are the union.

Two consequences shape the design. First, because permissions are unioned, roles can be small and composable; a user gets capabilities from one role and data from another. Second, there is no deny. If any role grants access to a dataset, the user has it. Design for that.

Dataset permissions are created automatically when a dataset is created and named after it, so the permission list grows with the catalogue. Schema permissions (schema_access on [db].[schema]) cover every current and future dataset in that schema, which is the lever that makes the model scale.

The default roles and where they stop

Role What it grants Realistic use
Admin Everything, including security settings Two or three platform owners
Alpha Access to all data sources, create and edit charts and dashboards, no security settings Too broad for anyone in a multi-department deployment
Gamma Read charts and dashboards for data sources granted separately; no SQL Lab The right base for viewers and most builders
sql_lab SQL Lab access, layered on another role Analysts who write SQL
Public Applied to unauthenticated visitors Empty, unless you publish public dashboards deliberately

Alpha is the problem. It carries all_datasource_access, so an Alpha user sees every dataset in every database connected to Superset. The moment two departments share an instance, Alpha is a policy violation waiting to be discovered. The design below uses it for nobody.

The model: capability roles plus data-domain roles

Split roles into two families and assign at least one from each.

Capability roles: what a person can do

Role Built from Adds Removes
cap_viewer Gamma Nothing can_export on Chart and Dashboard if exports are restricted
cap_explorer Gamma can_explore on Superset, can_write on Chart (own charts), can_read on Dataset Dashboard editing
cap_builder Gamma Everything in explorer, plus can_write on Dashboard, can_read on CssTemplate
cap_analyst Gamma + sql_lab SQL Lab, can_sql_json, can_csv, saved queries Dashboard editing unless also a builder
cap_curator cap_builder can_write on Dataset, can_read on Database (to create virtual datasets and manage the catalogue) Database connection editing
cap_admin Admin

None of these grant any data. A user with only cap_builder can create a dashboard but has no datasets to put on it.

Data-domain roles: what a person can see

One role per data domain, granting schema_access on the schemas that belong to it, and nothing else:

Role Grants
data_finance schema_access on [warehouse].[finance], schema_access on [warehouse].[finance_marts]
data_sales schema_access on [warehouse].[sales]
data_ops schema_access on [warehouse].[operations]
data_hr_restricted datasource_access on specific HR datasets, not the schema, because the schema also contains payroll
data_shared schema_access on [warehouse].[shared_dims], the calendar, geography and product dimensions everyone needs

Prefer schema access. A new dataset created in the finance schema is visible to data_finance holders automatically, which is what the finance team expects. Use dataset-level access only when a schema contains a mix of sensitivities, and treat that as a signal to split the schema in the warehouse.

Putting them together

A finance analyst holds cap_analyst, data_finance, data_shared. A sales operations dashboard builder holds cap_builder, data_sales, data_ops, data_shared. A board member holds cap_viewer and data_finance. Adding a marketing department is one new data role and a mapping in the identity provider. Adding a new capability (say, alert creation) is one change to one capability role.

With five capability roles and ten domains you have fifteen roles, not fifty, and every one has a name a security reviewer can read.

Designing this for your actual org chart?

The capability/data-domain split above is the pattern; mapping it onto your specific teams, data domains, and SSO groups is the part that takes a workshop, not a blog post. A Superset Architecture Review does that mapping.

Book a Superset Architecture Review

Dashboard permissions

Data-domain roles decide which datasets a user can query. They do not by themselves control which dashboards appear in the list. Two mechanisms do:

Default behaviour. A user sees a dashboard if they have datasource access to every dataset on it (or the dashboard is published and they have access to at least one chart’s data, depending on version). This falls out of the data roles and is usually enough.

Dashboard RBAC. With the DASHBOARD_RBAC feature flag on, a dashboard owner can attach roles to a dashboard under its properties. Users in those roles can view the dashboard even if they lack datasource access to its datasets, for that dashboard only. This is how you publish an executive summary built on restricted data to a wider audience without granting them the underlying tables.

python
FEATURE_FLAGS = {
    "DASHBOARD_RBAC": True,
}

Use it deliberately. Because it bypasses dataset permissions, a dashboard with an over-broad role attached is a data exposure. Reserve the right to attach roles to curators, and review attachments quarterly (see the checks section).

Row-level security

RBAC decides which tables. Row-level security decides which rows. Under Settings, Row Level Security, a rule attaches a SQL clause to datasets for roles:

  • Regular rules add a filter for the listed roles: region = 'EMEA' on the sales datasets for data_sales_emea.
  • Base rules apply to everyone except the listed roles, which is how you filter by default and exempt a headquarters role.
  • Clauses can use Jinja: owner_email = '{{ current_username() }}' for per-user filtering, with ENABLE_TEMPLATE_PROCESSING on.

RLS composes with the role design cleanly: data_sales grants the tables, data_sales_emea (a role with no permissions at all, used only as an RLS handle) restricts the rows. For customer-facing multi-tenant deployments the considerations are different and covered in multi-tenant RLS for embedded Superset.

SQL Lab and database-level controls

SQL Lab lets analysts run arbitrary SQL, subject to the schemas their roles grant. Controls that matter at scale:

  • Per database connection, under Advanced, SQL Lab: expose in SQL Lab (off for databases nobody should query ad hoc), allow DML (off everywhere except a sandbox), allow file uploads (off).
  • SQL_MAX_ROW and DISPLAY_MAX_ROW in config, and per-database query timeouts, so one analyst cannot take down the warehouse.
  • schema_access is what limits which schemas appear in SQL Lab’s schema dropdown; database_access alone exposes every schema, so grant schemas not databases.
  • Consider user impersonation on the connection for warehouses that support it (Snowflake, BigQuery, Postgres roles). Superset then runs the query as the logged-in user, and the warehouse’s own audit log attributes it.

Feeding roles from SSO

Hand-assigning fifteen roles to five hundred people is where good designs die. Every capability and data role should map from a group in the identity provider through AUTH_ROLES_MAPPING, with AUTH_ROLES_SYNC_AT_LOGIN = True so that a group change takes effect at the next login. The Okta guide shows the mechanics; the design here is what the mapping targets:

python
AUTH_ROLES_MAPPING = {
    "bi-viewers": ["cap_viewer", "data_shared"],
    "bi-builders": ["cap_builder", "data_shared"],
    "bi-analysts": ["cap_analyst", "data_shared"],
    "finance-all": ["data_finance"],
    "sales-all": ["data_sales"],
    "sales-emea": ["data_sales_emea"],
    "bi-platform-admins": ["cap_admin"],
}

Group membership is now managed by the people who manage groups, with the identity provider’s approval workflow and audit trail, and Superset simply reflects it.

Roles as code

Clicking permissions into fifteen roles is error-prone and unrepeatable. Two ways to define them in configuration:

FAB_ROLES lets you declare roles as lists of regex pairs over view menu and permission names:

python
FAB_ROLES = {
    "cap_viewer": [
        [".*", "can_read"],
        ["Dashboard", "can_read"],
        ["Chart", "can_read"],
        ["Superset", "can_dashboard"],
        ["Superset", "can_slice"],
    ],
}

Roles declared here are created and kept in sync on superset init, and the config file becomes the policy document.

A provisioning script using the security manager’s API (add_role, find_permission_view_menu, add_permission_role) for the data-domain roles, run as part of deployment, reading the schema list from a YAML file. This is what we do for larger deployments because schema permissions are data-driven and a regex over [warehouse].[finance.*] is fragile.

Either way, keep the definition in version control and treat a role change like a code change: reviewed, tested in staging, deployed.

The checks that keep it honest

A role model drifts. These queries against the metadata database, run monthly, catch the usual drift:

  • Nobody holds Alpha. SELECT u.username FROM ab_user u JOIN ab_user_role ur ON u.id = ur.user_id JOIN ab_role r ON r.id = ur.role_id WHERE r.name = 'Alpha'. Expected: empty.
  • Admin count is small and known. Same query for Admin. Expected: the platform owners, nobody else.
  • No role grants `all_datasource_access` except Admin. Check ab_permission_view_role joined to permissions.
  • Every dataset’s schema is covered by exactly one data role, so that a new dataset is not accidentally visible through two domains.
  • Dashboard RBAC attachments list, with owners, for review.
  • Users with no data role (they can log in and see nothing), which usually means an SSO group mapping is missing.
  • Users not seen for 90 days, for deactivation.

Put the results in a dashboard. Superset is quite good at those.

Where to start if you have the everyone-is-Alpha deployment

  • Inventory users, roles and dataset permissions from the metadata database.
  • Define the data domains from the warehouse schemas, and the capability roles from what people actually do (most are viewers).
  • Create the new roles alongside the old ones, map SSO groups, and give a pilot department the new roles in addition to their old ones.
  • Verify the pilot sees what they should and nothing more, then remove their old roles.
  • Repeat per department. Remove Alpha last, once the last department is migrated.

Expect two to four weeks for a five-hundred-user deployment, most of it in conversations about who should see what, which is the conversation the deployment should have had at the start.

Frequently Asked Questions

Why is giving everyone the Alpha role a problem?

Alpha grants access to every dataset in the deployment, including ones added after the role was assigned, plus the ability to edit them. At fifty users that is untidy. At five hundred it means no one can answer the question an auditor actually asks, which is who can see a given table and why. The role model below exists so that question has an answer that does not depend on memory.

How many roles does a 500-user Superset deployment need?

Fewer than most teams expect, if the roles compose. Splitting them into capability roles (what a person can do) and data-domain roles (what a person can see) means a new department is one new data role rather than a full set of duplicates. A deployment of this size typically lands between twelve and twenty roles in total, not one per team.

Does row-level security replace role-based access control?

No, it narrows it. RBAC decides whether someone reaches a dataset at all; RLS decides which rows they see once they are there. They are designed to work together: a data-domain role grants the tables, and an RLS rule attached to a permission-free handle role restricts the rows. Using RLS alone to do both leaves the dataset itself reachable.

Can Superset roles be assigned automatically from Okta or Entra ID?

Yes, and they should be at this scale. Map every capability and data role to a group in the identity provider through AUTH_ROLES_MAPPING, and set AUTH_ROLES_SYNC_AT_LOGIN = True so a group change takes effect at the user’s next login. Access is then granted and revoked where the rest of your joiners-and-leavers process already lives.

Build It With Andolasoft

Role design is the second thing we look at in a Superset Architecture Review, after authentication: who has Alpha, how datasets are granted, whether RLS is doing what people think it is, and what the drift checks find. It is a fixed-scope, five-day review with a written report. If you would rather the role model were maintained for you, alongside patching and monitoring, that is Managed Support.

If you are looking at an everyone-is-Alpha deployment and an audit date, talk to us. We will map your current roles and dataset grants, show you where the real exposure is, and give you a fixed-scope plan to the model described above.
How to Add Collaboration Features to Apache Superset

Apache Superset has become one of the most widely deployed open-source analytics platforms in the world. It connects to virtually any SQL database, renders rich interactive dashboards, and costs nothing per seat. But teams that adopt it quickly discover a gap: Superset ships without built-in Apache Superset collaboration features. Analytics is a team sport, yet Superset, out of the box, is built for viewing, not for discussing. There are no dashboard comments and no way to annotate a chart. There is also no folder tree to organise a growing library of dashboards.

The result is familiar to anyone who has run a review meeting from a BI tool. Someone screenshots a chart, pastes it into an email or chat thread, and circles the anomaly in a paint tool. The discussion about the data happens everywhere except next to the data. Context is lost, and decisions go undocumented. Three weeks later, nobody remembers why anyone queried the number or what the team agreed.

This article explains what Superset offers natively, plus three practical ways to add Apache Superset collaboration features on top of it. It also shows how Andolasoft builds them as clean, upgrade-safe extensions for enterprise clients.

What Superset Supports Natively, and Where the Gaps Are

Superset’s native collaboration surface is real but thin. Dashboards can be shared by link and published or kept as drafts. Ownership controls who can edit them. Tags let you label dashboards and filter the list page. Role-based access control and row-level security govern who sees what. Alerts and reports can be emailed or rendered in a dashboard on a schedule.

What is missing is the conversational layer: no inline comments, no visual markup, no review workflow, and no hierarchical folders. Tags can stand in for folders on the list page. But business users outside BI tools find a flat, filterable list a poor substitute for a browsable library. These gaps are consistently the top adoption complaints from non-technical stakeholders.

Three Ways to Add Apache Superset Collaboration Features

1. Pinned Comments and Visual Annotations on Dashboards

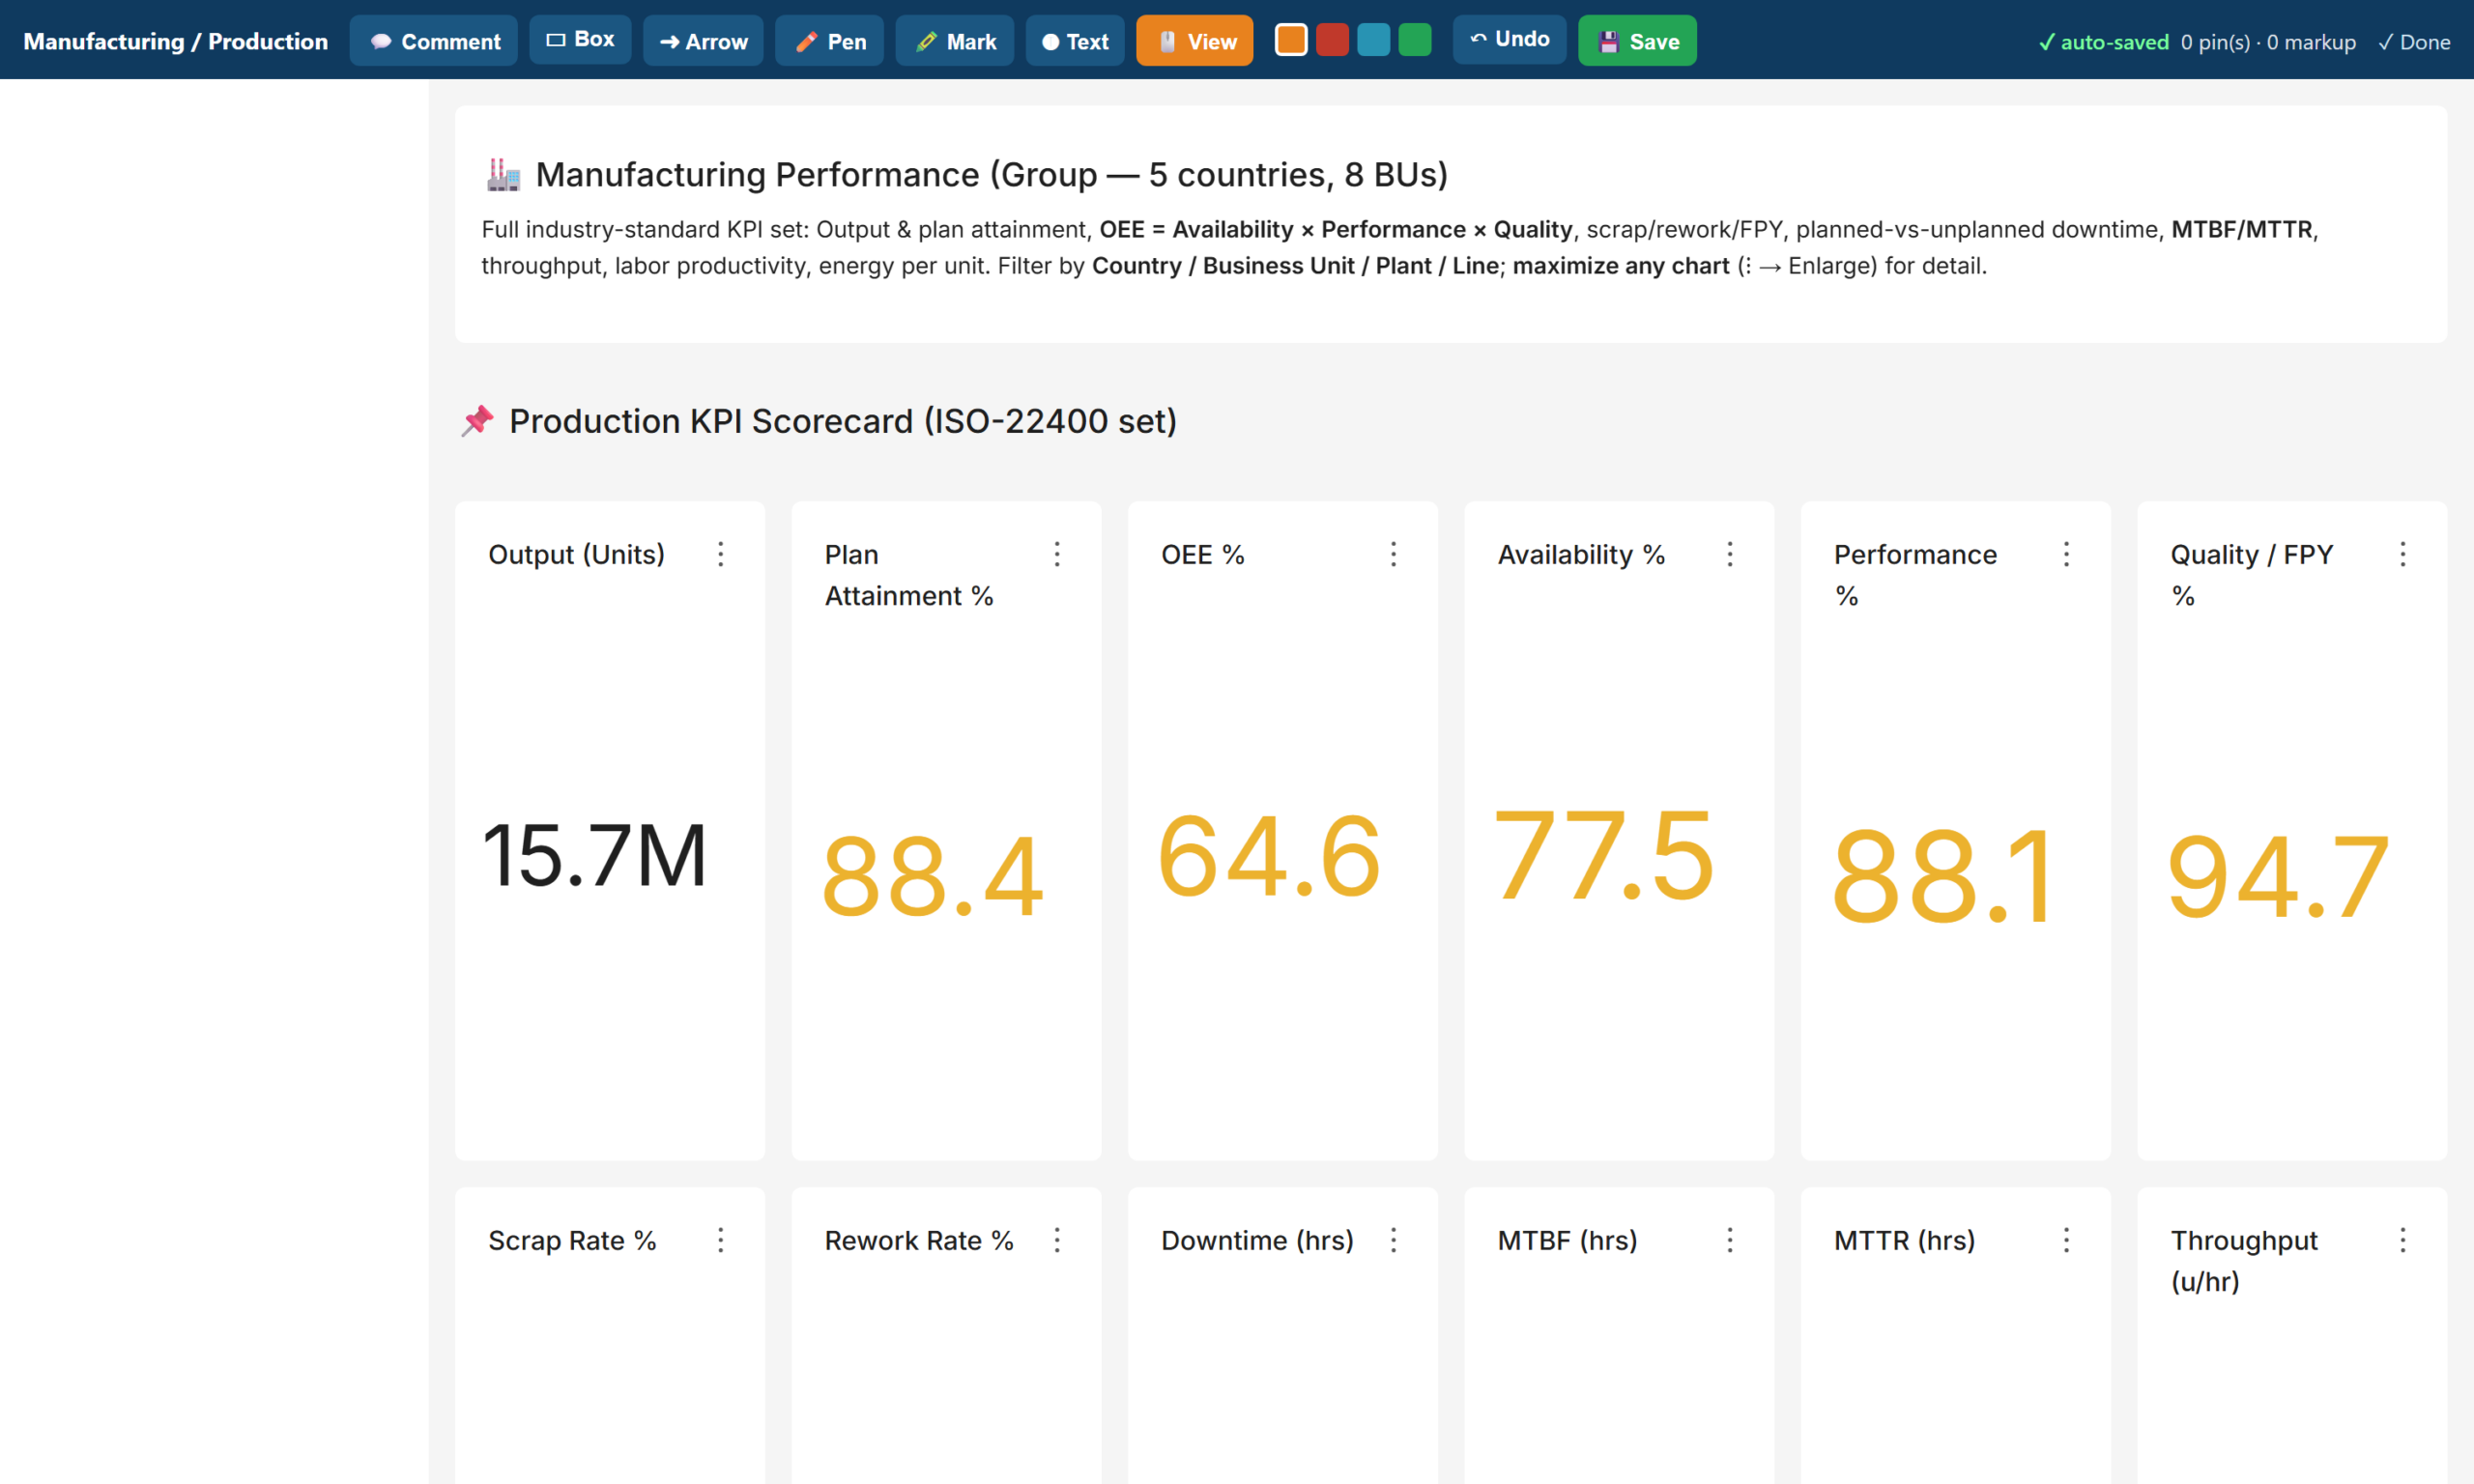
The highest-value addition is an in-dashboard markup layer. A reviewer opens a dashboard and clicks the exact chart in question. They pin a comment there, with a priority and a status, so the team can track it to resolution. Alongside pins, a drawing toolkit adds boxes, arrows, freehand marks, highlights, and text. Reviewers can mark up the live dashboard the way they would mark up a PDF. They can then save the annotation set for others to see.

Mechanically, a lightweight companion app delivers this feature inside Superset itself. It renders the target dashboard in an overlay and stores pins and drawings in your own database. Because it runs behind Superset’s session, the system attributes every comment to an authenticated user. And because it reuses Superset’s authentication, enabling Single Sign-On for Superset also enables it for the markup layer. Reviewers who never build charts just need a URL, their corporate login, and a pencil.

collaboration_markup

2. Folder-Style Navigation with Previews, Tags, and Search

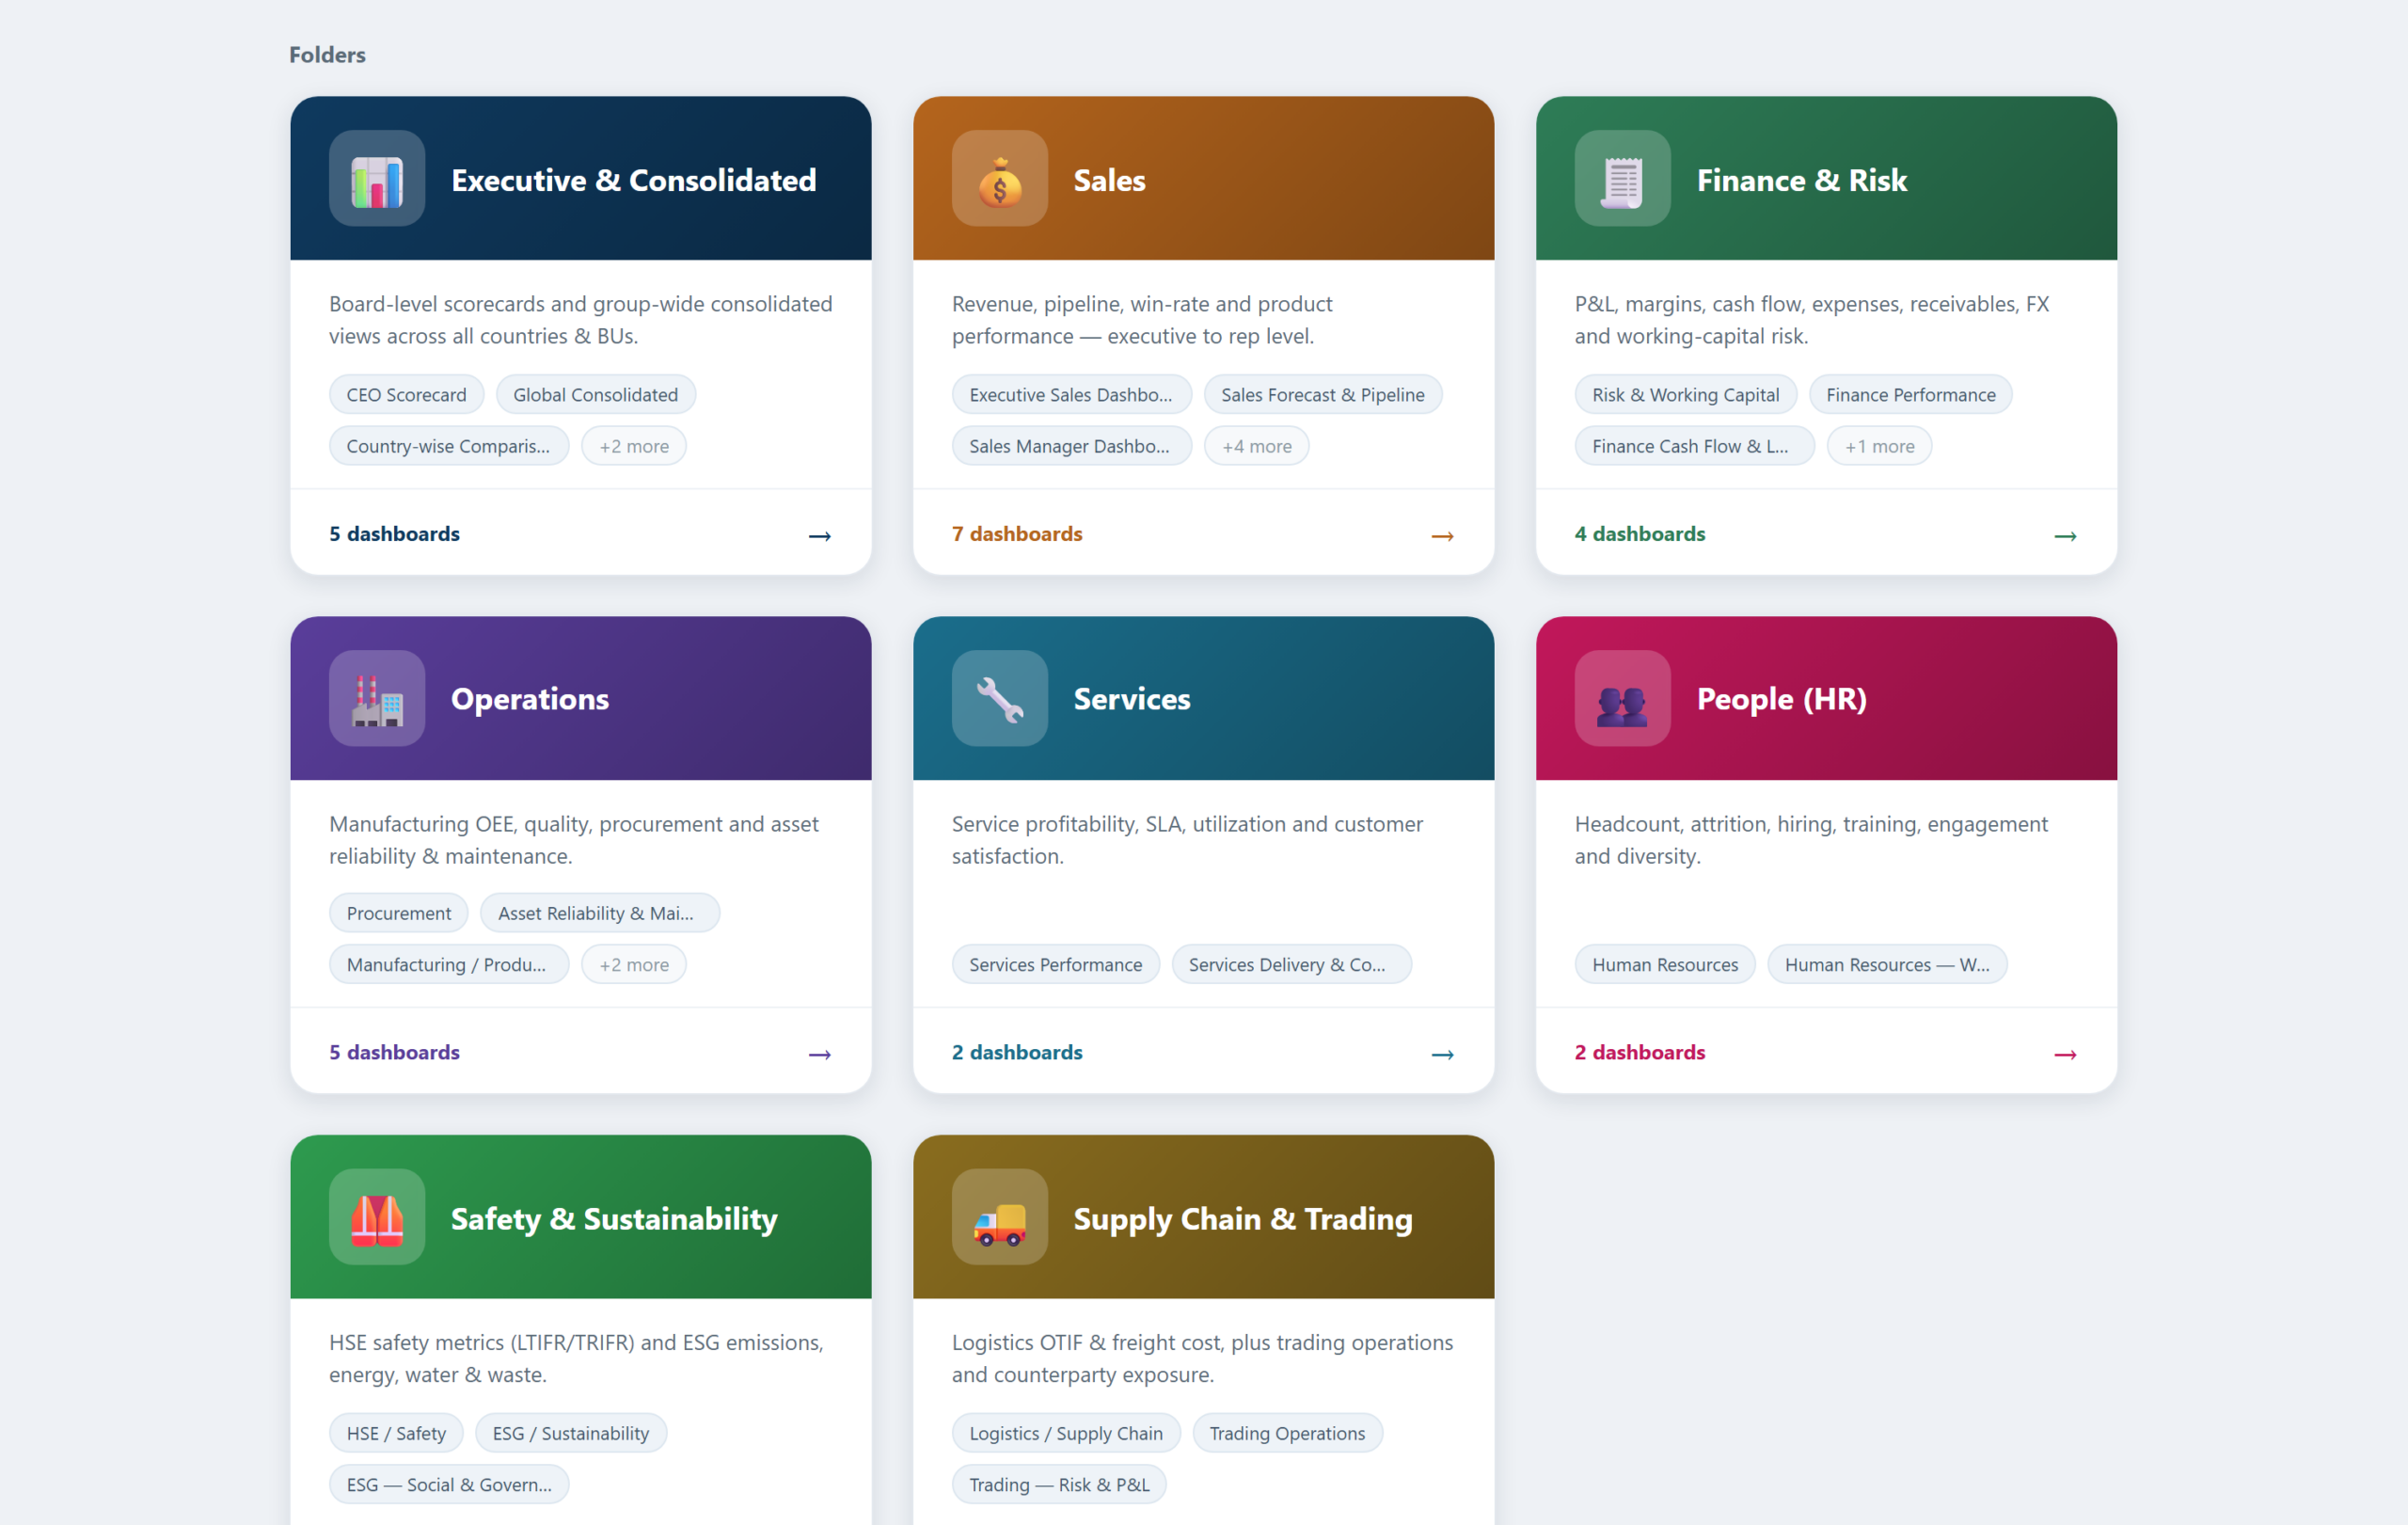
The second addition solves discovery. A folder app presents the dashboard estate as a set of coloured folder cards, one per function. Examples include Executive, Sales, Finance, and Operations. Opening a folder shows each dashboard as a card with a live preview thumbnail, its tags, and a chart count. Clicking a card opens a full preview with a jump-through to the real dashboard. A search box filters across every folder by title or tag.

collaboration_folders

The important design decision: folders generate live from the dashboard titles and tags already in Superset. The library maintains itself. Publish a new dashboard, and it appears in the right folder immediately, complete with its preview and tags. It’s instantly searchable too. No curator required.

3. Tags, RBAC, and Row-Level Security as the Governance Layer

Collaboration without governance becomes noise. The third layer is configuration, not code. A tag taxonomy, organised by department and by audience, powers both the native list filters and the folder app. Roles separate admins, editors, and viewers. Row-level security lets a country manager see their country and a business-unit head see their unit. Single Sign-On ties all of it to the corporate identity provider. Together, these controls make the collaborative layer trustworthy: every comment is attributable, and nobody annotates data they should not see.

How Andolasoft Builds Apache Superset Collaboration Features, Upgrade-Safely

The naive way to add features to Superset is to fork it and edit the source. That works until the next Superset release, at which point every upgrade becomes a merge conflict. Our implementations follow a stricter rule: never patch core.

  • Extensions, not forks: Flask blueprints deliver the comment, annotation, and folder apps alongside Superset. They use its session, authentication, and metadata, but touch none of its source files.
  • Your data, your database: pins, drawings, and folder definitions live in your PostgreSQL database. The team versions and backs them up with everything else.
  • Upgrade-safe by construction: we modify nothing in the core. A Superset version upgrade becomes a container-image bump plus a regression pass, not a re-implementation.
  • Security inherited, not duplicated: the apps inherit Superset’s login, so SSO, roles, and row-level security apply automatically.

What Changes for the Team

  • Reviews happen in context: feedback lands on the exact chart, with an author and a timestamp. It replaces the old screenshot thread.
  • Meetings get shorter: pre-meeting comments mean the meeting starts at the decision, not at the description of the problem.
  • Nothing falls through the cracks: comments carry a status. The team either resolves each query or leaves it visibly open.
  • The library invites browsing: non-technical users navigate a folder library with previews and search instead of a flat list. Adoption follows.

Frequently Asked Questions

Can You Add Apache Superset Collaboration Features Like Comments?

Not natively. In practice, though, a lightweight companion app can add Apache Superset collaboration features to any dashboard. These include pinned comments and visual annotations. It runs on Superset’s own login and SSO, and stores everything in your own database.

Does Superset have folders for dashboards?

No. Tags provide folder-like filtering on the dashboard list. A custom folder app can add full card-based navigation, with live previews, tags, and search. It generates automatically from the dashboards you already have.

Will Apache Superset Collaboration Features Break on Upgrade?

Not if you build them as extensions rather than source patches. Flask-blueprint apps that sit alongside an unmodified Superset core survive version upgrades with a simple regression pass.

Do reviewers need a Superset licence or training?

Superset is open source, so there are no licences at all. Reviewers need only a corporate login and a URL. Commenting and annotating require no chart-building knowledge.

Build It With Andolasoft

Andolasoft designs and deploys governed, board-ready analytics platforms on Apache Superset for manufacturing and industrial companies. See our detailed Superset dashboard templates for manufacturing KPIs for an example. Our BI practice covers the full lifecycle: KPI modelling to global standards (ISO 22400, SCOR, GRI) and data modelling with conformed dimensions. It also includes department dashboards with direction-aware RAG scorecards, row-level security, and Single Sign-On. Folder navigation and the Apache Superset collaboration features covered above round out the platform. Because Superset is open source, the entire platform runs without per-seat licence fees. The investment goes into your KPIs, not licences.

If your leadership team is still waiting for month-end spreadsheets, talk to us. We will stand up a working demo on a representative dataset and walk your stakeholders through it. Then we’ll give you a clear, fixed-scope plan to production.

Predictive BI: Transforming Raw Data Into Future Insights

Predictive BI is reshaping how organizations anticipate market trends, customer behaviors, and operational bottlenecks.

According to a recent Gartner report, companies adopting predictive intelligence can improve decision-making speed by up to 50%.

In today’s hyper-competitive landscape, traditional reporting is no longer enough.

Leaders now require real-time forecasting to stay ahead — making Predictive BI: Transforming Raw Data Into Future Insights more urgent than ever.

In this post, you’ll learn:

  • Why predictive intelligence is mission-critical
  • Practical frameworks and implementation strategy
  • Real-world results from transformations

Whether you’re a CTO, founder, product manager, or engineering lead — you’ll walk away with a blueprint for implementing Predictive BI with confidence and measurable ROI.

Predictive BI The Future of Decision-Making

Why Predictive BI Matters Now

As organizations scale, data grows exponentially — from IoT sensors and SaaS interactions to ERP and CRM workflows. Without predictive intelligence, businesses risk inefficiencies and lost opportunities.

What Happens Without Predictive BI?

  • Overstocked inventory and lost sales due to poor forecasting
  • Reactive operations, leading to downtime and inefficiencies
  • Cybersecurity threats that go unnoticed until it’s too late

Where Predictive BI Is Making an Impact

  • Healthcare: Predict patient admissions to reduce staffing gaps
  • Logistics: Optimize routes to reduce fuel consumption by 15%
  • SaaS: Improve conversion rates by 20% using behavioral analytics
  • Manufacturing: Detect maintenance needs before equipment fails

The Cost of Doing Nothing

Legacy BI systems create:

  • Data silos
  • Manual reporting delays
  • High operational costs

Modern enterprises need a scalable, integrated Predictive BI ecosystem — guided by experts who understand both technology and industry context.

Predictive BI Framework & Best Practices

Implementing Predictive BI is not a one-time task — it’s a structured journey. Below is the recommended implementation roadmap.

1. Define Clear Business Objectives

Align predictive goals to measurable KPIs such as churn reduction, seasonal demand forecasting, or supply chain efficiency.

2. Conduct Data Inventory & Quality Assessment

Audit data sources (ERP, CRM, IoT sensors, finance systems) and evaluate them based on:

  • Completeness
  • Accuracy
  • Timeliness

High-quality input = reliable predictions.

3. Choose Scalable Architecture

Adopt Lambda or Kappa architecture to support:

  • Real-time analytics
  • Batch processing
  • Cost efficiency

4. Select the Right Tech Stack

Select the Right Tech Stack

5. Iterative Model Development

Use Agile sprints, A/B testing, and continuous retraining to maintain accuracy as data evolves.

6. Embed Security & Compliance

Implement:

  • Encryption
  • RBAC
  • Audit logs
  • SOC 2/HIPAA compliance

7. Monitor, Optimize & Operationalize

Deploy model drift alerts and automated dashboards.

Quick Wins:

  • Add anomaly alerts for trend deviations
  • Enable self-service access for end users

8. Build a Data-Driven Culture

Train teams, provide documentation, and make insights accessible.

Do’s & Don’ts of Predictive BI

Do: Invest in data governance early
Don’t: Overcomplicate early models

Do: Containerize deployments (Kubernetes, Docker)
Don’t: Ignore model explainability — stakeholder trust matters

How Andolasoft Accelerates Predictive BI Adoption

Andolasoft offers end-to-end expertise:

  • Custom Web & Mobile Engineering: Predictive dashboards and apps
  • SaaS Product Engineering: Scalable multi-tenant architecture
  • BI, AI & ML Solutions: End-to-end model pipelines
  • Application Modernization: Migration to cloud-native stacks
  • Cloud, DevOps & Automation: Predictive CI/CD and automated retraining

With Andolasoft as a technology partner, organizations avoid:

  • Data silos
  • Costly architectural missteps
  • Underutilized analytics investments

Customer Success Example

  • Challenge: Predict patient admission volumes to reduce ER wait times.
  • Solution: Real-time forecasting deployed with cloud-native predictive framework.

Results in 6 Months:

  • 40% reduction in ER wait times
  • 25% improvement in staffing efficiency
  • 30% infrastructure savings through modernization

MedSecure now scales confidently with predictive capabilities embedded across operations.

Key Takeaways

  • Predictive BI converts raw data into forward-looking insights that drive measurable business impact.
  • High-quality data, scalable architecture, and governance are foundational.
  • Continuous model training and DevOps practices ensure accurate forecasting.
  • Security, compliance, and explainability must be included from day one.
  • Working with Andolasoft accelerates deployment and avoids implementation pitfalls.